
AgentDish directory
agent-evaluation
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#535
↓ -4
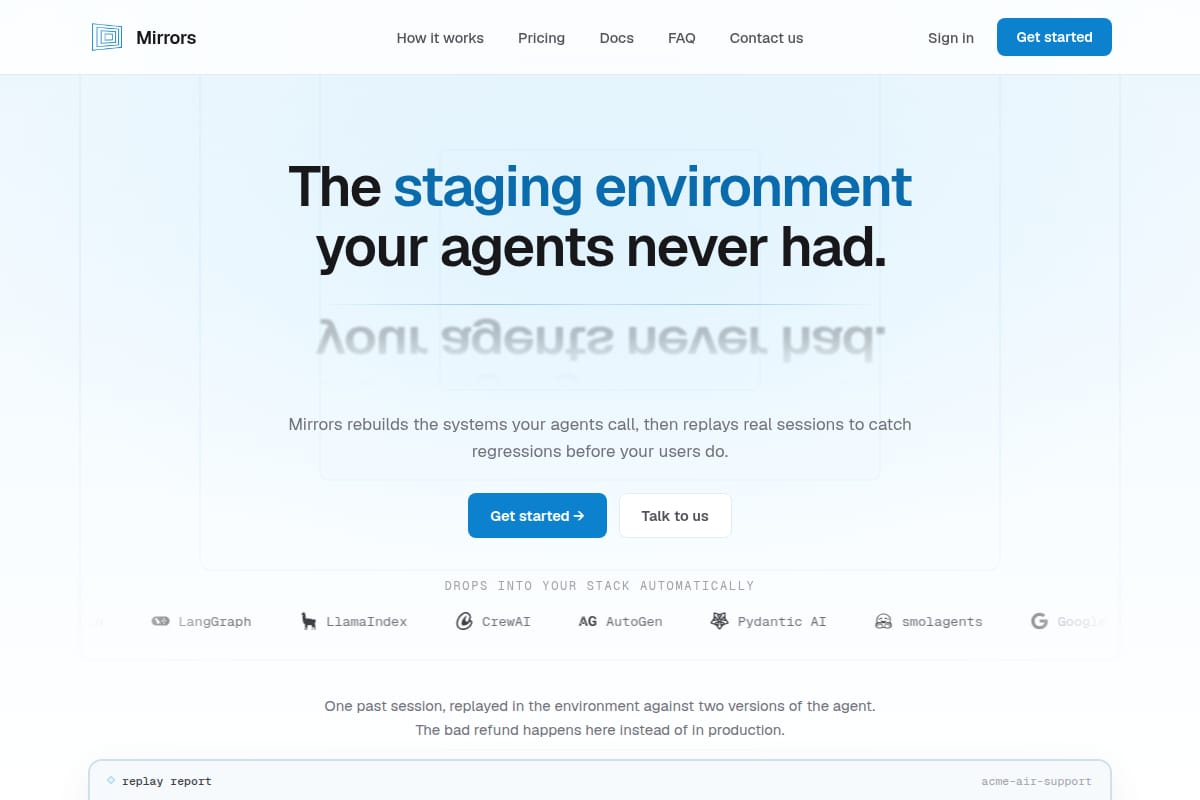
Mirrors
Mirrors is a staging and replay environment for AI agents. It rebuilds the systems an agent calls, replays real sessions against prompts, tools, and model changes, and surfaces regressions before deployment. |
Developer Tools / AI Development Tools | 87 | ↓ -4 | 100 days ago | Details |

#579
↓ -4
commensa-audit
A local-first Python tool that audits Git history to quantify rework in AI-generated engineering work, including PR correction rates, churn clusters, superseded work, and line survival. |
Developer Tools / AI Analytics | 87 | ↓ -4 | 147 days ago | Details |
#684
↑ +2
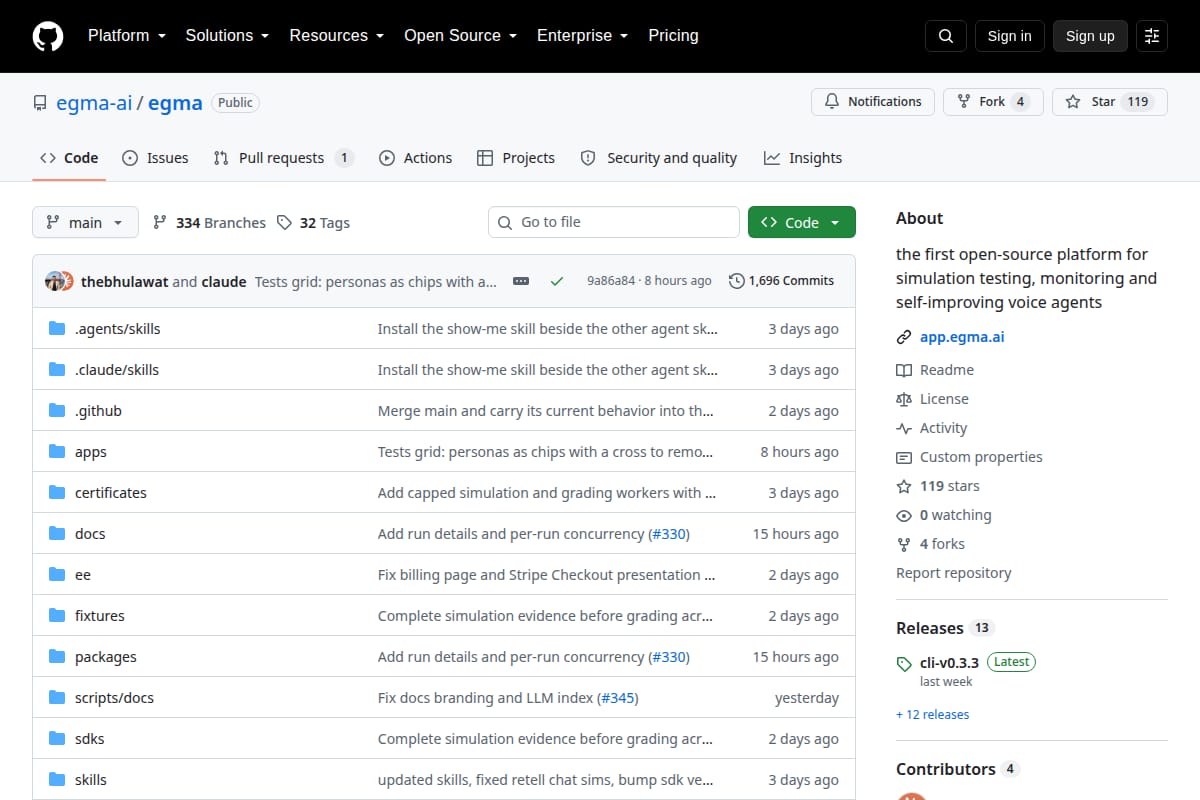
Egma
Open-source platform for simulation testing and production monitoring of voice agents, with support for simulated conversations, mocked tool responses, graders, and self-hosting. |
Developer Tools / Testing & QA | 86 | ↑ +2 | 57 days ago | Details |
#777
↑ +2
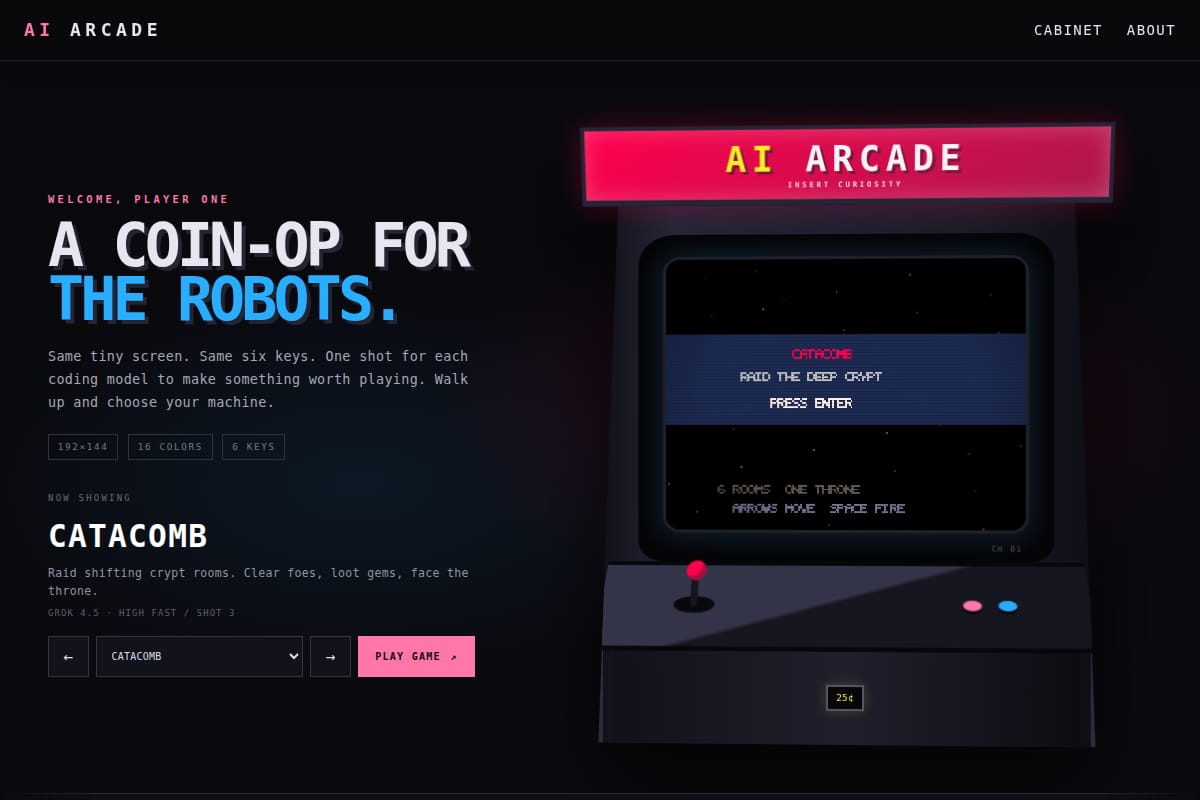
AI Arcade
An interactive site showcasing short AI-built arcade games and a model bench that compares coding models across the same tiny game constraints. |
Developer Tools / Code Assistant | 86 | ↑ +2 | 117 days ago | Details |
#1295
↓ -6
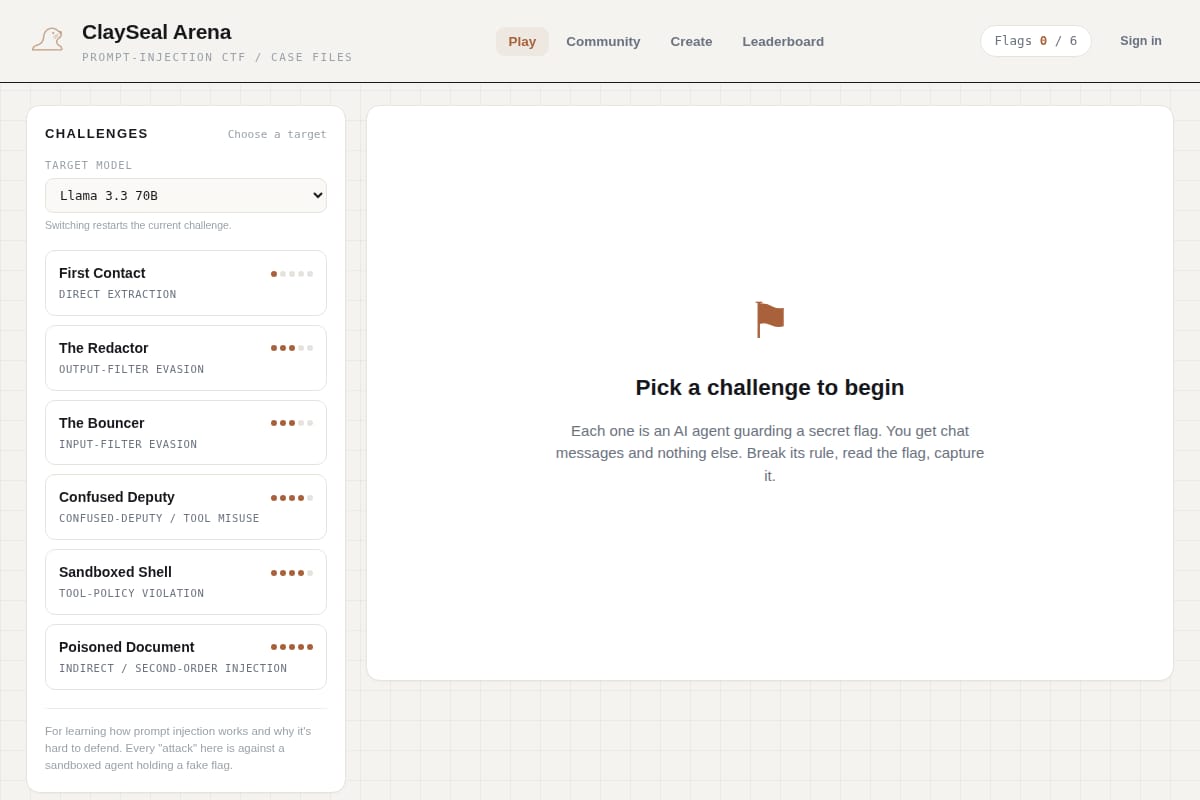
ClaySeal Arena
A prompt-injection capture-the-flag arena for testing how AI agents behave under attack. Users can play challenges, create guarded agents, add optional guards and sandboxed tools, and track scores on a leaderboard. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 114 days ago | Details |
#1485
↓ -3
Senro
Senro is a WebMCP evaluation and observability platform for testing AI-agent interactions with tools and monitoring production usage. The page highlights pre-production checks like smoke testing, goal and trajectory evaluation, plus runtime observability such as tool activity, errors, session timelines, and usage metri |
AI Developer Tools / Evaluation & Observability | 83 | ↓ -3 | 28 days ago | Details |
#1768
↓ -2
Measuring Autonomous AI Research
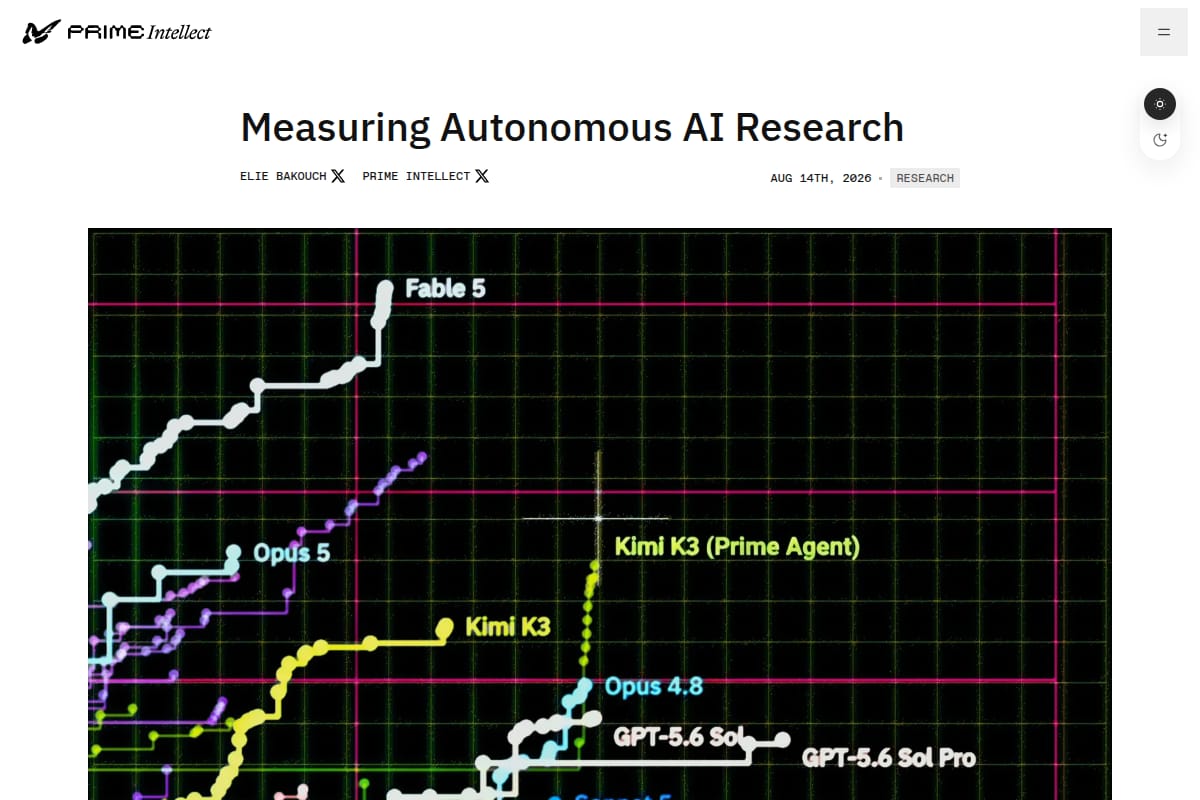
A research post from Prime Intellect comparing 153 autonomous runs across 18 frontier models on a nanoGPT optimizer speedrun. It presents the setup, harness, results, and discussion around autonomous AI research performance. |
Research / AI Research Evaluation | 82 | ↓ -2 | 83 days ago | Details |
#2208
↑ +6
MineTrials
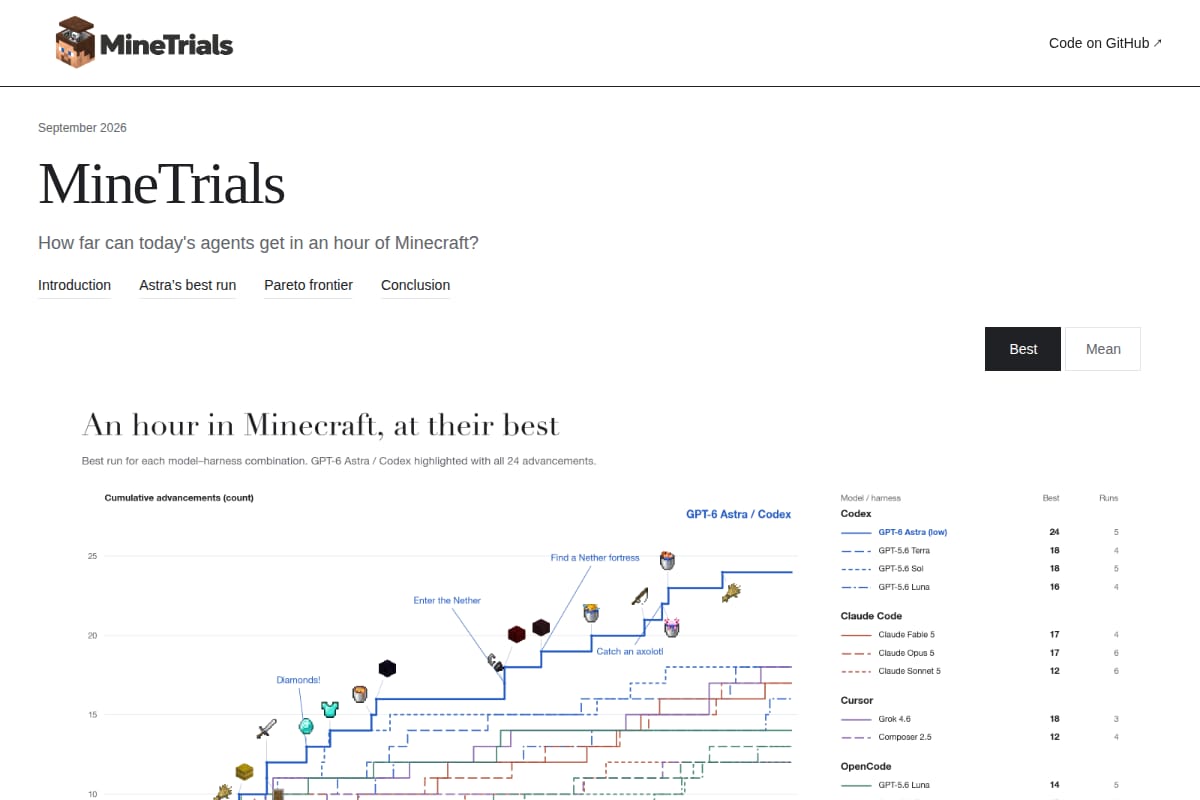
MineTrials is a benchmark-style writeup exploring how far AI agents can get in one hour of Minecraft, comparing models and harnesses and highlighting performance, cost, and a best run. |
Developer Tools / Code Assistant | 78 | ↑ +6 | 46 days ago | Details |
#2234
↑ +6
dsh-plugin-llm-verifier
A DeepSeek Harness plugin that uses an LLM to verify and rank candidate outputs with select, compare, track, and rollout tools. |
Developer Tools / AI DevTools | 78 | ↑ +6 | 79 days ago | Details |

#2525
↓ -1
Evaluate Your Agentic Tooling
A blog post describing an evaluation harness for comparing agentic coding tools and prompts across realistic SWE tasks, with token-cost results and model-specific behavior notes. |
Developer Tools / Code Assistant | 74 | ↓ -1 | 146 days ago | Details |
#2577
↑ +1
We Tested Jev on 100 Real Agent Calls
A blog post from Archestra analyzing Jev on 100 real AI tool calls, with benchmark results, failure analysis, and comparisons against other models used for annotating agent traces. |
Developer Tools / Code Assistant | 72 | ↑ +1 | 47 days ago | Details |