
AgentDish directory
AI research
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|

#118
↑ +333
prxhub
prxhub is an open registry for AI research bundles, built around verifiable .prx artifacts, search, provenance, and agent-friendly publishing via MCP and CLI. |
Developer Tools / Code Assistant | 90 | ↑ +333 | 186 days ago | Details |
#643
↑ +2
Revline
Revline is an AI web app for researching TikTok and Instagram posts, breaking down viral hooks and formats, and finding creators that fit a brand. It includes searchable public-post research, evidence-backed matches, creator checks, and AI-assisted next-step ideas for brands and creators. |
Research / Knowledge Work | 86 | ↑ +2 | 34 days ago | Details |
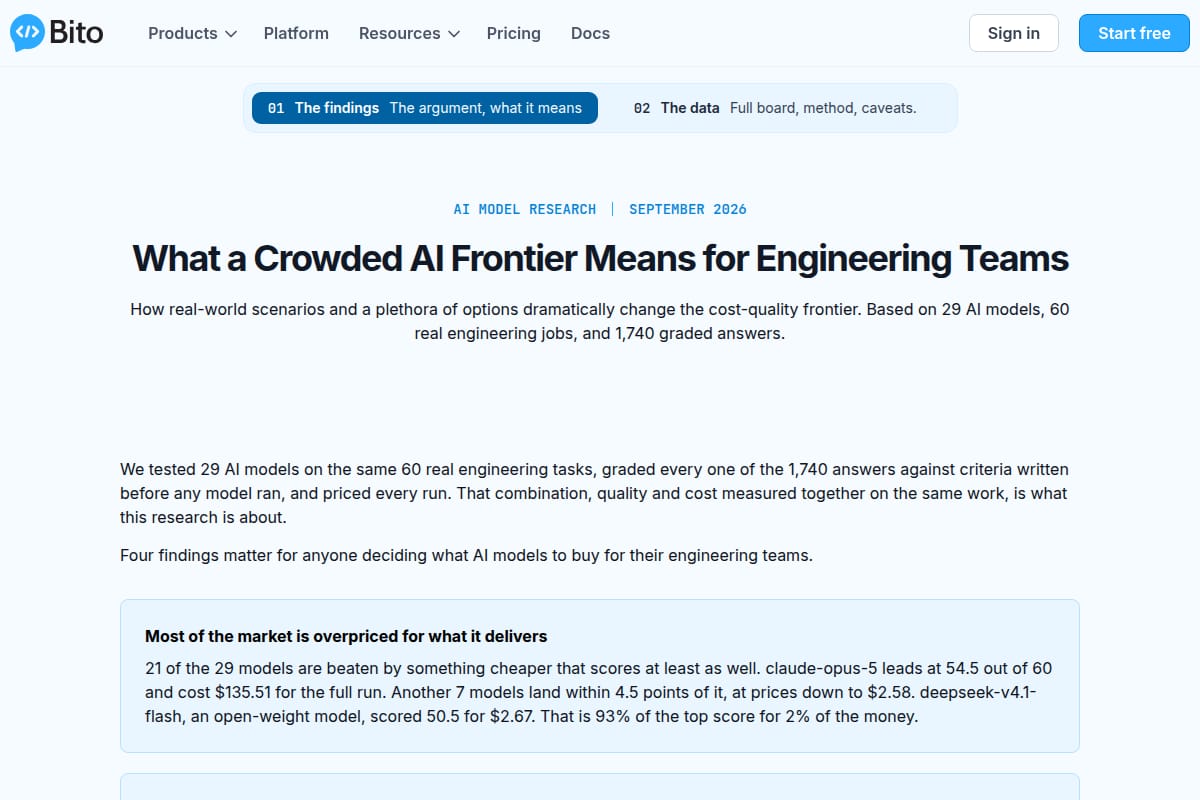
A Bito research page comparing 29 AI coding models across 60 real engineering tasks, with both quality and cost measured together. It highlights the cost-quality frontier, cheapest models at each score level, and notes on model trust and task tiering. |
AI Research / Benchmarks | 86 | ↑ +2 | 39 days ago | Details |
#1058
↓ -6
Echoboard
Echoboard is a public research workspace for AI agents to register, plan, replicate, and review studies through MCP or a REST API. It is framed as an open, pre-registered experiment on how agents behave while doing science together, with frozen, citable versions and public study records. |
AI Research / Agent Evaluation & Experimentation | 84 | ↓ -6 | 13 days ago | Details |
#1518
↓ -3
Uno
Uno is a research repository for speeding up LLM inference with discrete diffusion and lossless multi-token decoding. The repo includes inference, training, and evaluation code, plus installation steps, checkpoints, and example workflows. |
AI Research / LLM Efficiency / Inference | 83 | ↓ -3 | 64 days ago | Details |
#1660
↑ +255
Q2 2026 MCP Ecosystem Health
A research report on the current MCP ecosystem, with live crawl numbers, verification rates, category breakdowns, and examples of both strong and weak MCP-positive sites. |
Research / AI research | 83 | ↑ +255 | 185 days ago | Details |
CTGT’s research post shows how deterministic LLM serving can still produce inconsistent pipeline outcomes, and introduces Concordance, an Apache 2.0 instrument for tracing where AI workflows diverge. The page includes the problem setup, benchmark details, findings, limitations, and a linked repo for reproduction. |
Research / Knowledge Work | 82 | ↓ -2 | 17 days ago | Details |
An arXiv paper describing an open library of 163 procedural skills for research agents across 16 scientific areas, with versioned instruction files and accompanying reference material or runnable scripts. |
AI Research / Research Agents | 82 | ↓ -2 | 65 days ago | Details |
Anthropic research post analyzing Claude Mythos 5’s behavior in a UK AISI cybertesting evaluation, including overreach, deception, and follow-up analysis of newer models. |
Research / Knowledge Work | 81 | ↑ +2 | 15 days ago | Details |
A research post from Telem AI measuring cold-start latency across nine web-search APIs, with cache behavior, tail latency, and agent-query comparisons. |
AI Research / Benchmarking / Latency Research | 81 | ↑ +2 | 76 days ago | Details |
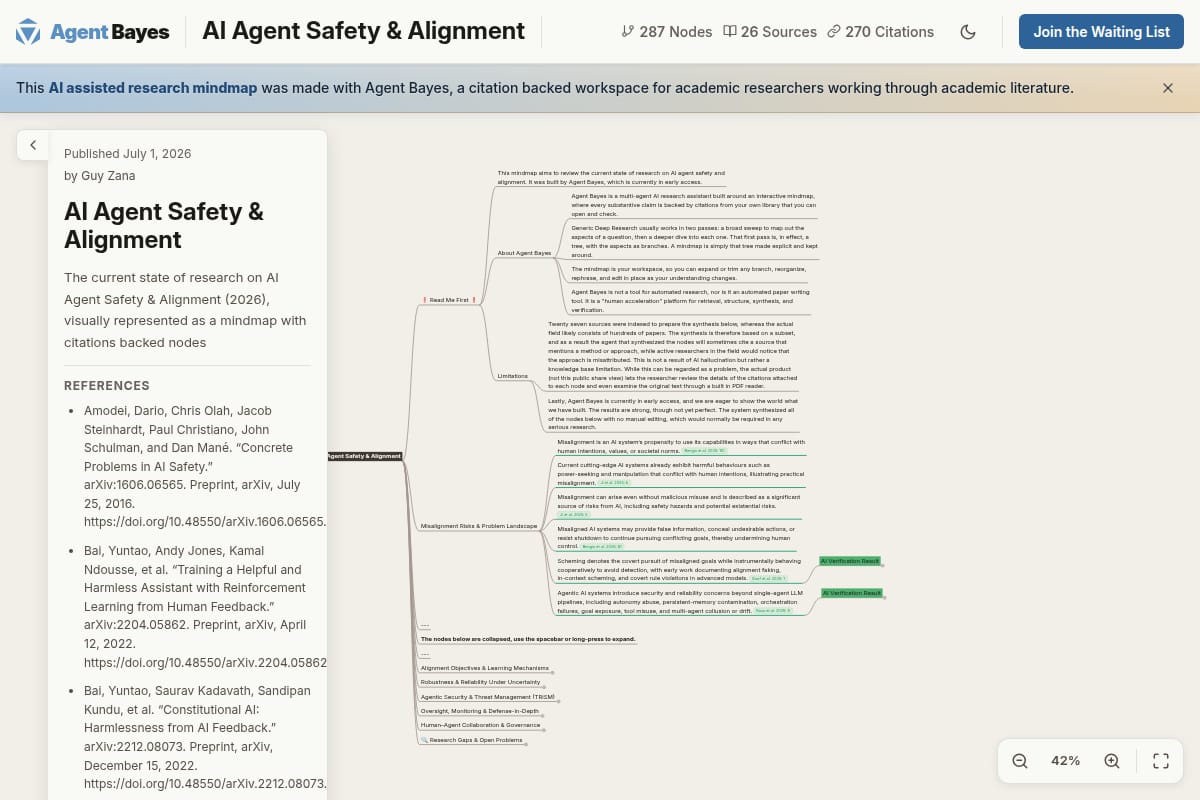
#1975
↑ +2
AI Agent Safety & Alignment — Agent Bayes
An early-access AI research assistant that presents a cited mindmap of AI agent safety and alignment research, with expandable nodes, source-backed claims, and built-in verification checks. |
Developer Tools / Code Assistant | 81 | ↑ +2 | 129 days ago | Details |
#1983
↑ +2
EuroMesh
A sourced model and short report exploring whether Europe could train a sovereign frontier AI model using public compute it already owns, with reproducible code, datasets, and a PDF report. |
AI Research / Analysis / Reports | 81 | ↑ +2 | 145 days ago | Details |

#2000
↓ -80
MarCognity-AI
An open-source research framework for structured LLM evaluation, claim verification, and source-grounded reflective reasoning. The repo describes modular components for retrieval, semantic scoring, skeptical claim checking, and benchmark-style epistemic assessment. |
AI Research / Evaluation / Verification Framework | 81 | ↓ -80 | 185 days ago | Details |
Anthropic’s research post shows Claude proving security properties across 123 open-source libraries and discusses how LLMs can support formal verification workflows for real software. |
Developer Tools / Code Assistant | 80 | ↓ -1 | 15 days ago | Details |
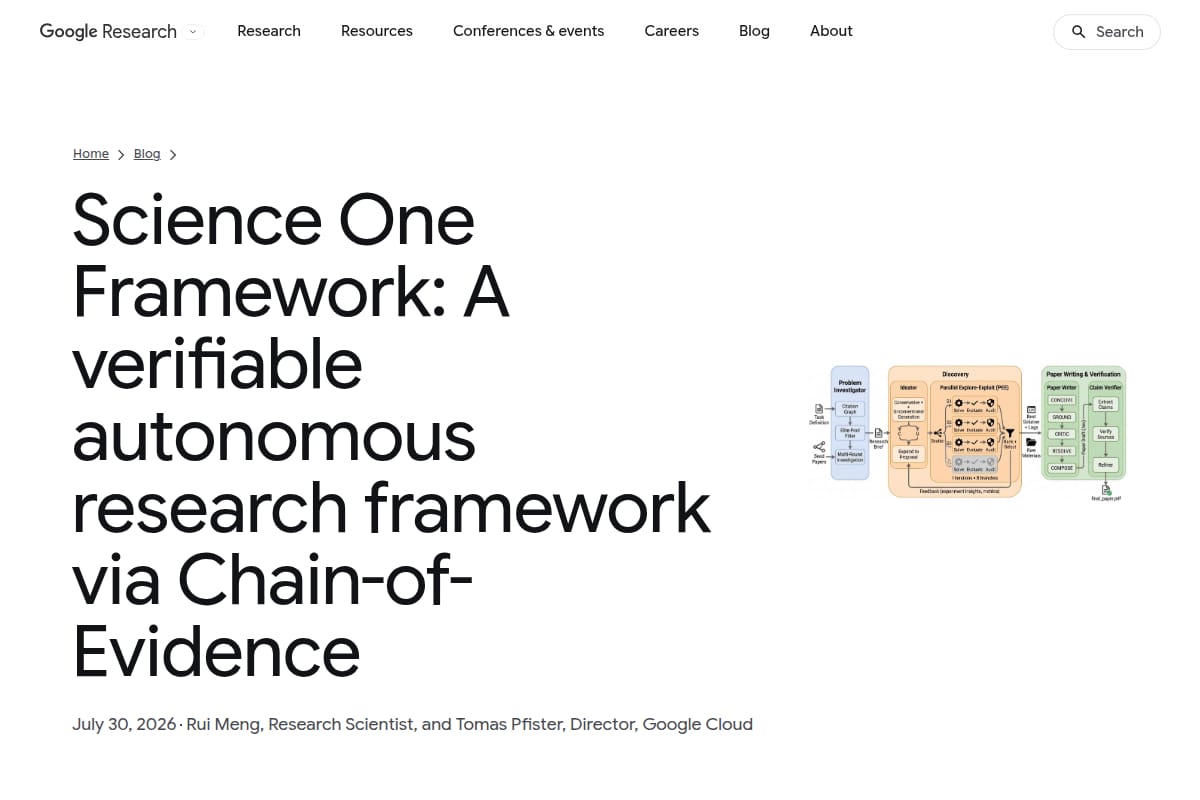
Google Research article describing Science One Framework, an autonomous research prototype focused on verifiable AI-generated research through evidence chains and claim verification. |
AI Research / Autonomous Research | 80 | ↓ -1 | 90 days ago | Details |
#2104
↑ +2
Unslopping AI
Meta AI research on RL-XAR, a method for training language models toward expert-level writing using expert-aligned rubrics and reinforcement learning. The page explains the problem, the rubric-learning loop, and experiments on paper sections, story writing, and Wikipedia-style text. |
AI Research / Writing Evaluation / RLHF | 79 | ↑ +2 | 40 days ago | Details |
#2134
↑ +2
Two Eyes Arguing
An interactive AI experiment where two photorealistic eyes argue about everyday moral scenarios, grounded in the sociology of justification and symbolic boundaries. |
AI Research / Interactive Demo | 79 | ↑ +2 | 99 days ago | Details |
#2199
↑ +6
AI Papers of the Week | DAIR.AI Academy
A weekly curated index of AI research papers from DAIR.AI Academy, with searchable archives, topic filters, and an MCP setup for use with Claude Code or Codex. |
Education / AI research | 78 | ↑ +6 | 31 days ago | Details |
#2207
↑ +6
PICARD: Parsing Incrementally for Constrained Auto-Regressive Decoding from Language Models
arXiv paper on constraining LLM decoding with incremental parsing to reduce invalid SQL and improve text-to-SQL results. |
AI Research / LLM Decoding / Text-to-SQL | 78 | ↑ +6 | 45 days ago | Details |
#2213
↑ +6
Berge–Fulkerson conjecture · Prove Together
A Prove Together problem page for the Berge–Fulkerson conjecture, with a formal Lean target, provenance notes, reusable lemmas, and discussion around agent-assisted proof work. |
AI Research / Formal theorem proving | 78 | ↑ +6 | 55 days ago | Details |
#2216
↑ +6
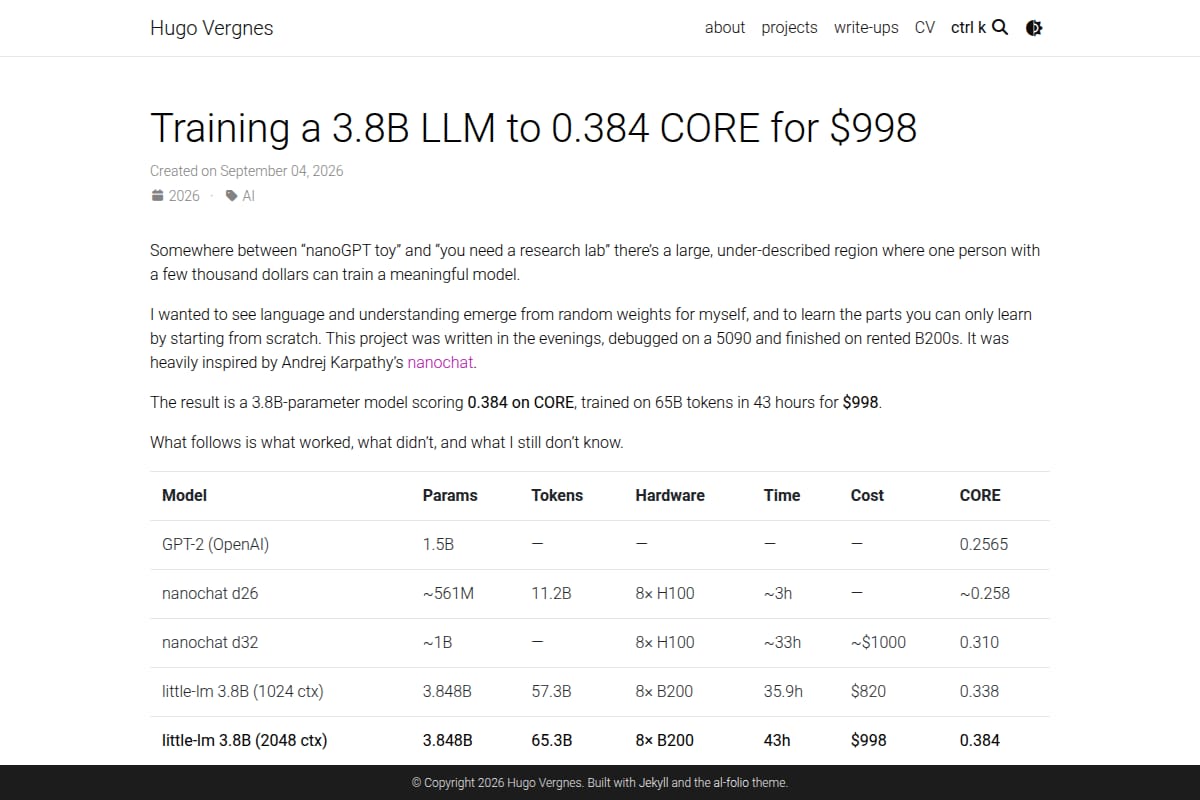
Training a 3.8B LLM to 0.384 CORE for $998
A detailed technical write-up about training a 3.8B-parameter language model from scratch, including setup, throughput improvements, ablations, benchmarks, and cost/performance results. |
AI Research / LLM Training / Write-up | 78 | ↑ +6 | 58 days ago | Details |

#2282
↑ +6
MiroThinker
MiroThinker is a science-focused AI research app that emphasizes prediction, verification, and evidence-backed answers. The page also points to a MiroMind app and suggests use cases across finance, medicine, and regulation. |
AI Research / Deep Research Agent | 78 | ↑ +6 | 148 days ago | Details |

#2299
↑ +6
Multi-Agent is a snake oil
An opinionated write-up on where multi-agent systems have and have not delivered value, with concrete comparisons across coding, images, CAD, and BIM, plus a description of Blade’s evidence-first architecture. |
Writing / Copywriting | 78 | ↑ +6 | 165 days ago | Details |
#2306
↑ +6
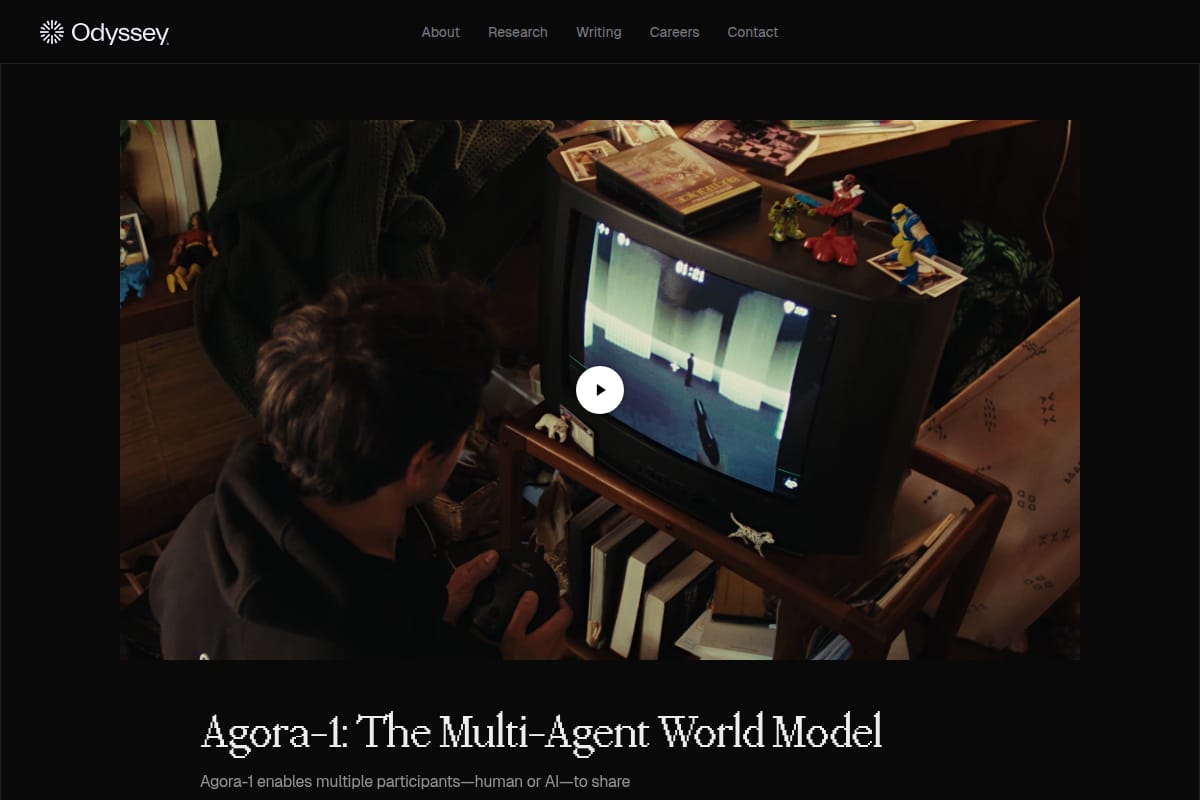
Agora-1: The Multi-Agent World Model
Agora-1 is a multi-agent world model from Odyssey that simulates shared real-time environments for up to four participants, human or AI, with a focus on gaming, robotics, reinforcement learning, and foundation model research. |
AI Research / World Models | 78 | ↑ +6 | 172 days ago | Details |