
AgentDish directory
benchmarking
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1126
↓ -6
ROCmFix
A utility for AMD GPU users running local AI on Windows or Linux. It detects the GPU, applies the right HSA_OVERRIDE_GFX_VERSION setting, offers health checks, and benchmarks Vulkan vs. HIP/ROCm for local LLM setups. |
Developer Tools / AI / ML Utilities | 84 | ↓ -6 | 48 days ago | Details |
A benchmark writeup comparing GraphQL-over-MCP and REST-over-MCP setups, showing lower token use and inference cost for GraphQL in agentic tasks. |
Developer Tools / AI Testing & Benchmarks | 84 | ↓ -6 | 51 days ago | Details |
A detailed post from pact0 about testing whether blank AI agents could complete a real product workflow, what failed, and the fixes they shipped after the audit. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 57 days ago | Details |
#1343
↓ -6
Caplets
Caplets is a developer tool that wraps MCP servers into smaller capability-based surfaces for coding agents. The site explains the workflow, setup, example capabilities like OSV, GitHub, and Sourcegraph, and includes benchmark results plus docs links. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 136 days ago | Details |

#1458
↓ -4
YourMemory
A persistent memory layer for AI agents, built as a standard MCP server with local setup, dashboard, and benchmark claims against other memory tools. |
Developer Tools / AI Memory / MCP | 84 | ↓ -4 | 185 days ago | Details |
#1504
↓ -3
jev-effort
A research project and proxy for Claude Code that chooses per-step reasoning effort with Jev while preserving the prompt cache. The repo includes benchmark results, a real-session measurement, and notes on how the mechanism works. |
Developer Tools / Code Assistant | 83 | ↓ -3 | 44 days ago | Details |
arXiv paper describing QUEST, an open family of deep research agents from 2B to 35B parameters, plus a synthetic-task training recipe and released models, data, and scripts. |
Research / AI Agents | 83 | ↓ -3 | 165 days ago | Details |
#1666
↓ -2
SAS (Symbiotic Autoprotection System)
A defensive AI auditing API for checking structural coherence, semantic rupture, and interaction stability, with a public demo, API docs, SDK install steps, and paid plans. |
Developer Tools / API | 82 | ↓ -2 | 11 days ago | Details |
A reproducible GitHub research repo comparing Codex reasoning-token usage between API and ChatGPT Pro access across 960 completed responses, with code, data, and verification steps included. |
Research / AI Benchmarks & Experiments | 82 | ↓ -2 | 32 days ago | Details |
#1693
↓ -2
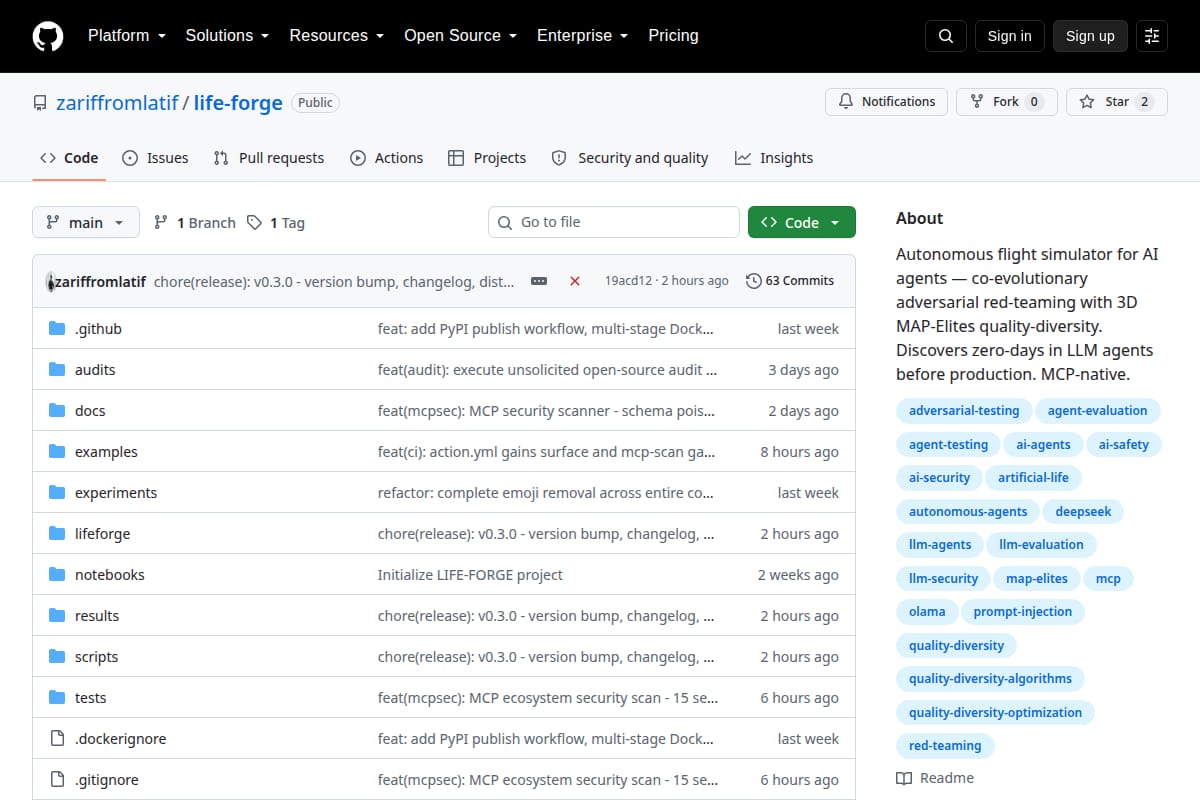
LIFE FORGE
A deterministic security scanner and adversarial flight simulator for AI agents, built for red-teaming LLM workflows and MCP-compatible setups. |
AI Security / Agent Red-Teaming | 82 | ↓ -2 | 35 days ago | Details |
#1720
↓ -2
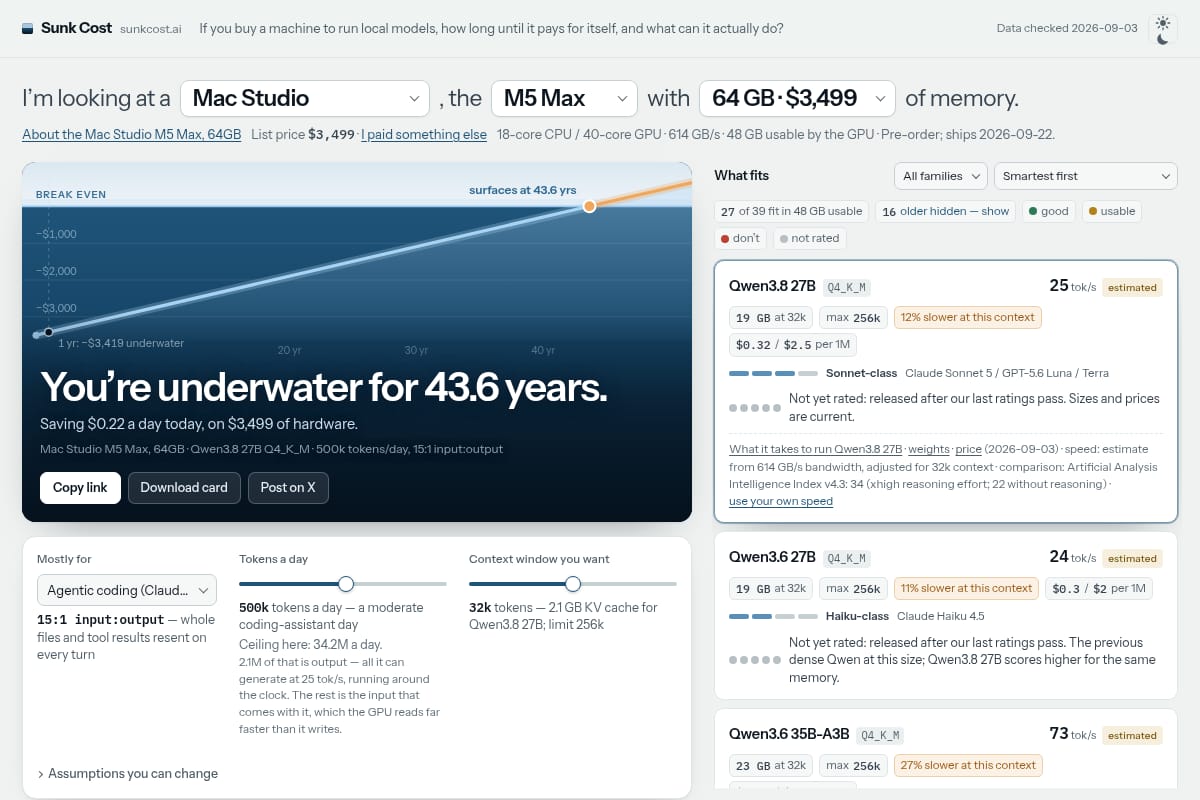
Sunk Cost
A web tool that estimates when a local LLM machine pays for itself versus using an API. It compares hardware options, model fit, speed, and break-even usage, with notes on assumptions and methodology. |
AI Tool / Local AI cost calculator | 82 | ↓ -2 | 53 days ago | Details |
#1723
↓ -2
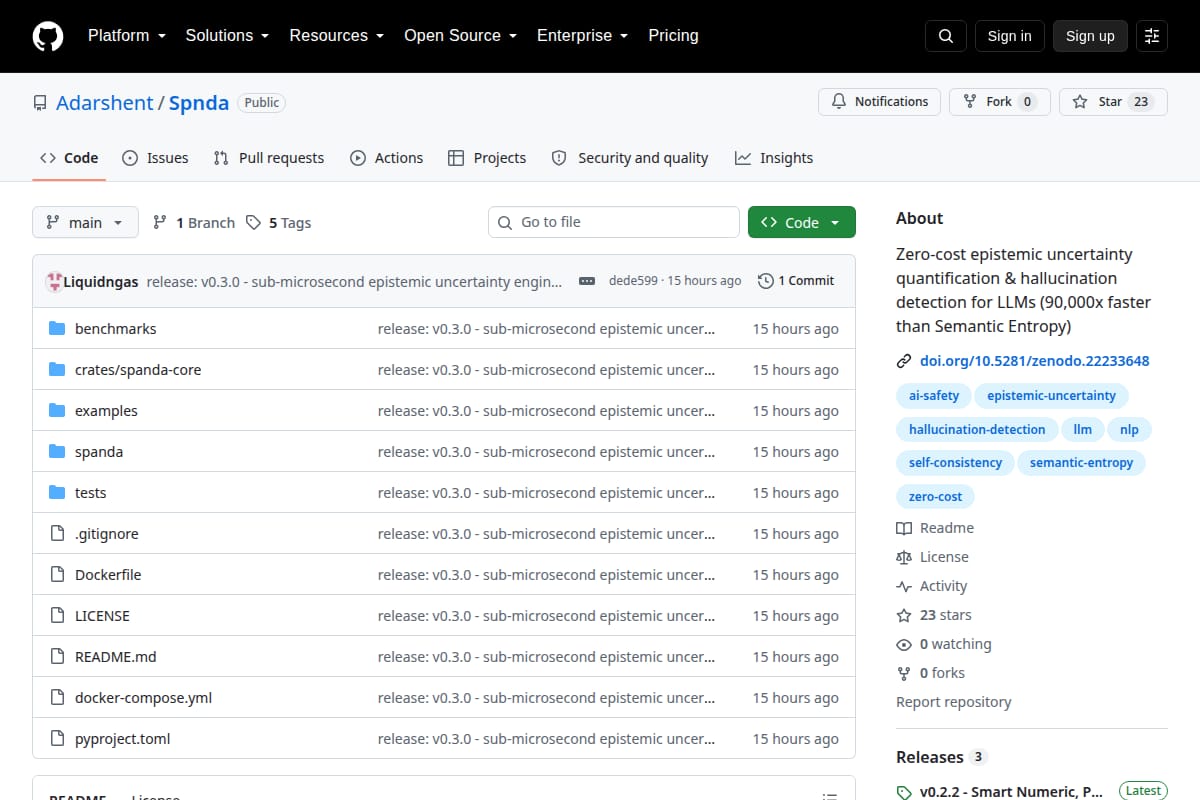
Spanda
Open-source LLM uncertainty and hallucination detection tool that estimates epistemic risk in microseconds using exact-match normalized entropy, with Rust gateway and Python package support. |
Developer Tools / Code Assistant | 82 | ↓ -2 | 56 days ago | Details |
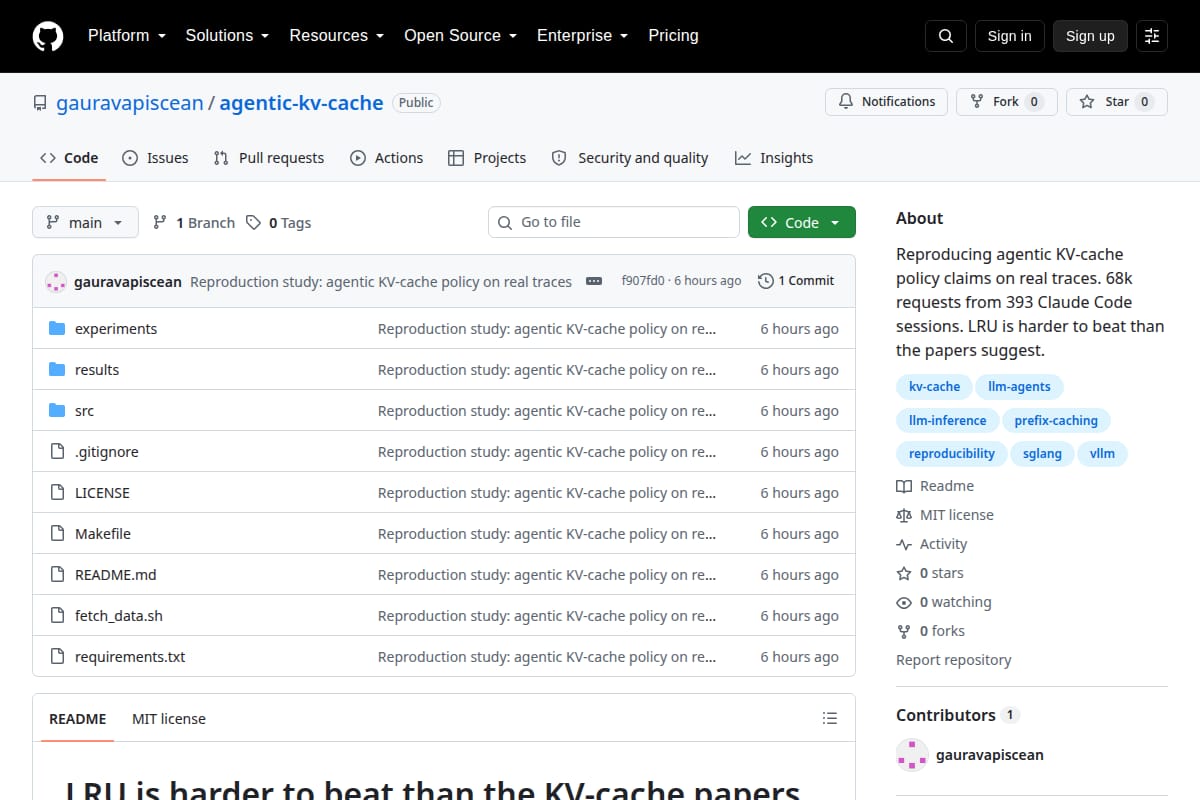
A research repo that replays real Claude Code and Mooncake traces to test prefix-cache eviction policies and compare them against LRU. |
Developer Tools / Code Assistant | 82 | ↓ -2 | 58 days ago | Details |
#1777
↓ -2
ExpertCache
Experimental page-aware Metal runtime and reproducibility harness for running oversized sparse mixture-of-experts models on Apple Silicon. The repo documents GPT-OSS 120B support, performance results on 64 GiB and 16 GiB machines, and the runtime/harness structure. |
Developer Tools / AI / ML Infrastructure | 82 | ↓ -2 | 90 days ago | Details |
#1861
↓ -2
clawmark
A local Rust CLI for A/B testing two CLAUDE.md files against a fixed SWE-bench Lite smoke set, with doctor, run, and report commands. |
Developer Tools / AI Benchmarking | 82 | ↓ -2 | 142 days ago | Details |
A write-up of a small benchmark comparing several public AI shopping assistants on niche fashion aesthetics. It shows where assistants confuse subcultures, drift toward neighboring styles, and miss brand-level signals needed for resale or outfit search. |
Writing / Copywriting | 81 | ↑ +2 | 10 days ago | Details |
#1953
↑ +2
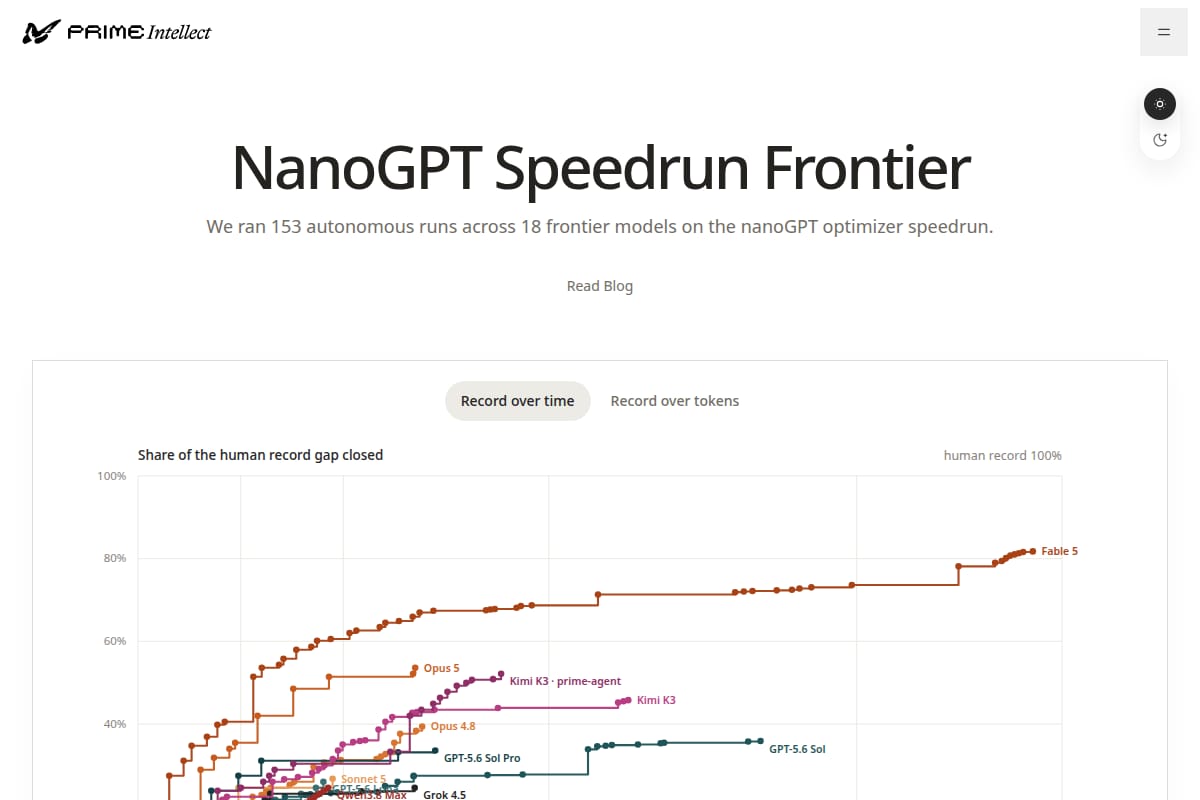
NanoGPT Speedrun Frontier
A research page comparing 153 autonomous runs across 18 frontier models on the nanoGPT optimizer speedrun, with rankings, trajectories, token/compute stats, and equal-budget comparisons. |
Research / Knowledge Work | 81 | ↑ +2 | 76 days ago | Details |
#1977
↑ +2
PSI KV Governor
Reference implementation for using Linux Pressure Stall Information to trim an LLM KV cache under memory pressure. The repo includes requirements, basic usage commands, a simulator, a llama.cpp runner, and benchmark scripts with example results. |
Developer Tools / AI Infrastructure | 81 | ↑ +2 | 132 days ago | Details |
#2110
↑ +2
Kairo
Open-source research workbench for fail-closed LLM inference routing based on measured GPU workloads. The repo documents Phase 1 results, reproducible experiments, quick-start commands, and a policy that only promotes exact measured workload buckets. |
Developer Tools / AI / ML Infrastructure | 79 | ↑ +2 | 54 days ago | Details |
#2118
↑ +2
Agent Lightning v1.0.1
A GitHub release for Microsoft’s Agent Lightning Skill, which helps coding agents optimize other AI agents using benchmarks and iterative improvements across prompts, tools, workflows, models, and reasoning settings. |
Developer Tools / AI Agents / Agent Training | 79 | ↑ +2 | 74 days ago | Details |
#2161
↑ +2
HoprLabs
A Python CLI and research toolkit for simulating AI training math before model training. It estimates memory, training time, token budget, config risks, benchmark speed, and reliability, with optional native Rust and C backends. |
Developer Tool / AI Research Toolkit | 79 | ↑ +2 | 134 days ago | Details |

#2188
↓ -275
Bonsai 1.7B: Apple Silicon Optimized Build
An Apple Silicon–optimized inference build of Bonsai 1.7B with custom Metal kernels, benchmark results, quick-start instructions, and a bundled OpenAI-compatible server. |
Developer Tools / Code Assistant | 79 | ↓ -275 | 185 days ago | Details |
#2216
↑ +6
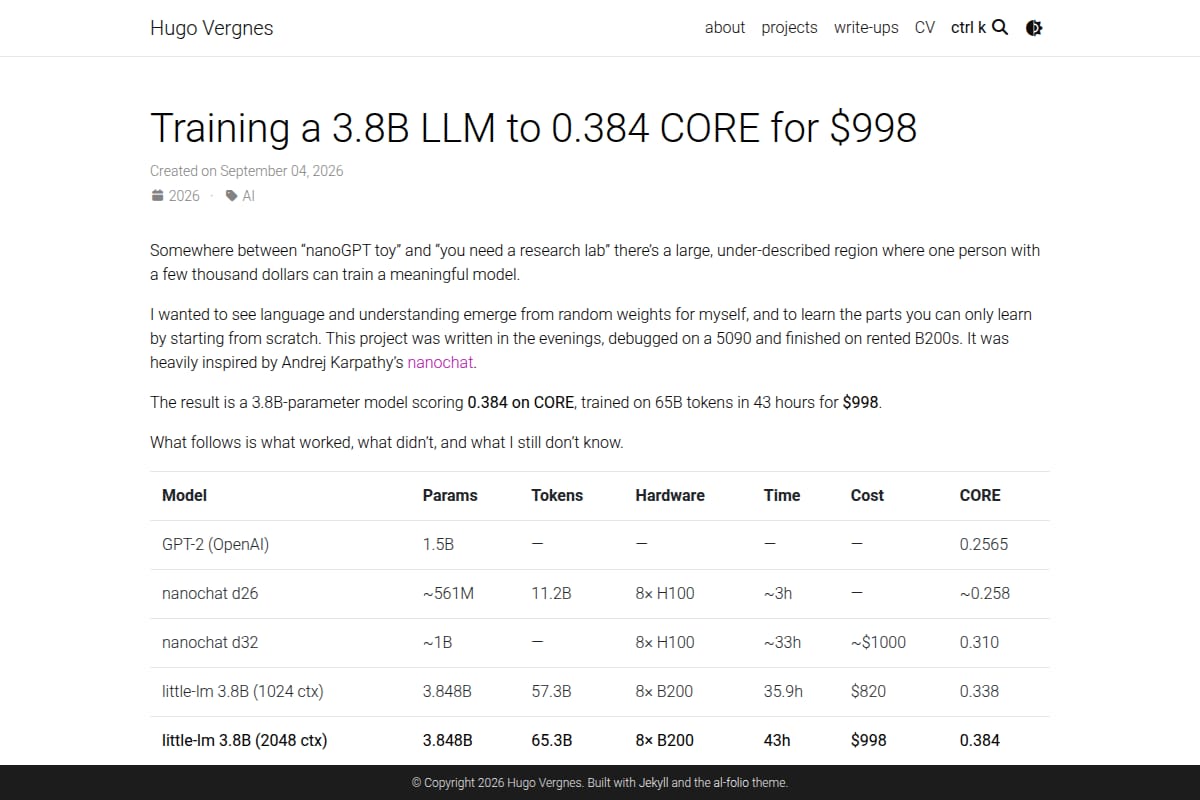
Training a 3.8B LLM to 0.384 CORE for $998
A detailed technical write-up about training a 3.8B-parameter language model from scratch, including setup, throughput improvements, ablations, benchmarks, and cost/performance results. |
AI Research / LLM Training / Write-up | 78 | ↑ +6 | 58 days ago | Details |

#2289
↑ +6
Verified RAG: every sentence checked
A blog post about verifiable RAG that benchmarks open-source NLI verifiers against Claude on RAGTruth and describes a Python library for sentence-level citation and claim verification. |
AI / RAG / Verification & Hallucination Detection | 78 | ↑ +6 | 158 days ago | Details |