
AgentDish directory
reinforcement-learning
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1242
↓ -6
nano-llm-posttraining
Minimal LLM post-training experiments on a single 8GB GPU, covering SFT, DPO, and GRPO with a focus on forgetting, seed variance, and RL behavior. |
AI Development / LLM Training & Fine-tuning | 84 | ↓ -6 | 98 days ago | Details |
#2101
↑ +2
StarSkirmish Hillclimb
A benchmark page for frontier models racing to write a StarCraft: Brood War bot in C++ using BWAPI and OpenBW, climbing tiers of increasingly strong Protoss opponents. |
AI Tools / Game AI | 79 | ↑ +2 | 35 days ago | Details |
#2104
↑ +2
Unslopping AI
Meta AI research on RL-XAR, a method for training language models toward expert-level writing using expert-aligned rubrics and reinforcement learning. The page explains the problem, the rubric-learning loop, and experiments on paper sections, story writing, and Wikipedia-style text. |
AI Research / Writing Evaluation / RLHF | 79 | ↑ +2 | 40 days ago | Details |

#2184
↑ +2
GenZ LLM
A small post-trained Qwen2.5-0.5B-Instruct model tuned to write in Gen Z slang, with training and inference notebooks plus dataset files in the repo. |
AI Models / Fine-Tuned LLMs | 79 | ↑ +2 | 180 days ago | Details |
#2245
↑ +6
EdotEnv (E.env)
Market-derived RL environments for training agents on quant trading and long-horizon planning under adversarial noise. |
AI/ML / Reinforcement Learning | 78 | ↑ +6 | 94 days ago | Details |
#2306
↑ +6
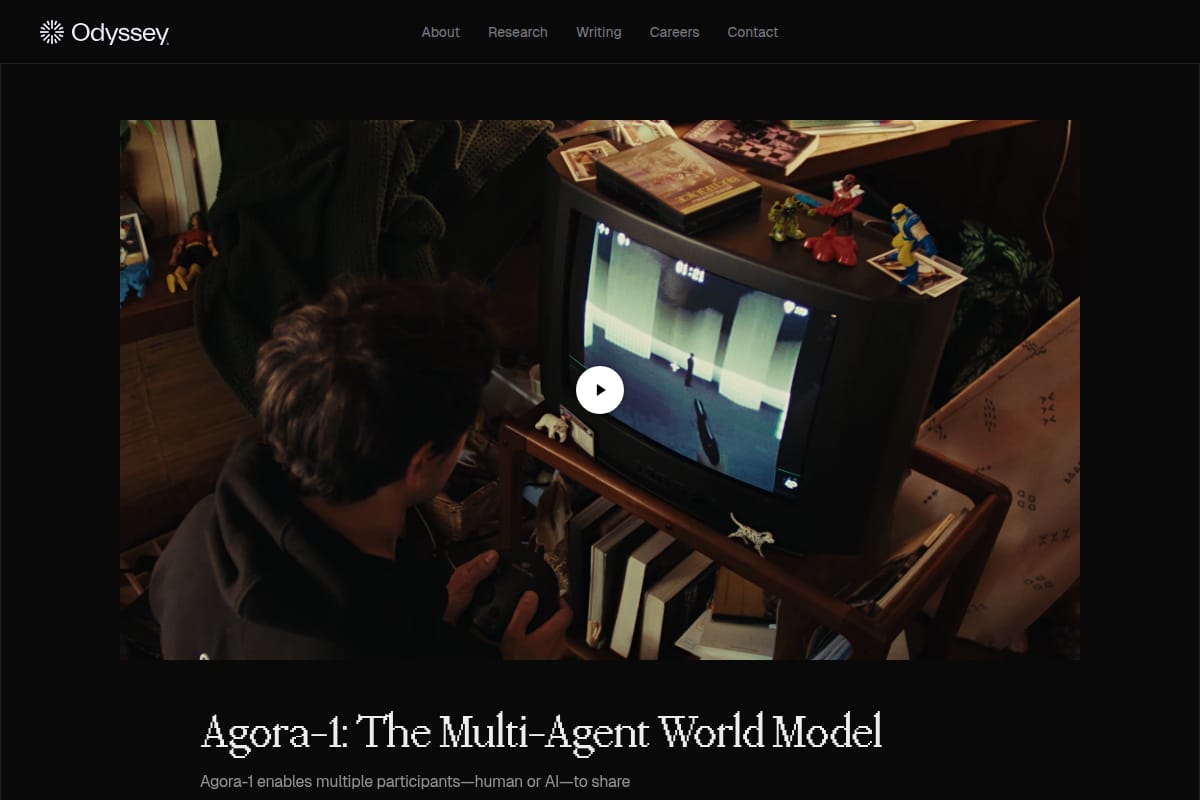
Agora-1: The Multi-Agent World Model
Agora-1 is a multi-agent world model from Odyssey that simulates shared real-time environments for up to four participants, human or AI, with a focus on gaming, robotics, reinforcement learning, and foundation model research. |
AI Research / World Models | 78 | ↑ +6 | 172 days ago | Details |
A paper page about FrogNano, a 4B coding agent trained with RL on roughly 1,500 SWE environments using synthetic tasks and no distillation from a larger model. |
Agents / Coding Agent | 74 | ↓ -1 | 59 days ago | Details |

A blog post describing a small reinforcement-learning agent trained with PPO to play and beat a Pokelike/Pokerogue-style game, including the input representation, model architecture, and training approach. |
Developer Tools / Code Assistant | 74 | ↓ -1 | 156 days ago | Details |

#2567
↑ +1
World Models for Planning Agents
An educational article explaining world models, latent states, dynamics learning, and planning for agents, with examples from gridworld, Dreamer, and MuZero. |
Writing / Copywriting | 73 | ↑ +1 | 174 days ago | Details |
arXiv paper on self-speculating LLM agents that predict their next tool call to hide tool latency and improve next-call Hit@1 while preserving task success. |
Research / AI Paper | 72 | ↑ +1 | 101 days ago | Details |