Research / AI Model Evaluation

Prompt-Conditioned Arabic–Hebrew Hybrid Artifact Formation in GPT-5.4

A Zenodo preprint reporting a 12,160-trial black-box evaluation of GPT-5.4 outputs under two prompt conditions, with detailed token-ceiling sweeps, control/ablation trials, and hash-chained verification.

Clear22/30
Useful18/30
Specific16/20
Complete16/20
Prompt-Conditioned Arabic–Hebrew Hybrid Artifact Formation in GPT-5.4 screenshot

Why it was accepted

The page clearly describes a research preprint about evaluating GPT-5.4 behavior, with a substantial experimental setup, quantitative results, and a linked repository. It is AI-adjacent and useful for people tracking model behavior, evaluation methods, and reproducible benchmark-style studies.
Weakness

The crawl shows the paper abstract and metadata, but not the full methods, dataset, code, or the actual repository contents, so a visitor cannot verify implementation details or reuse the evaluation directly from this page alone.

Review status

94 days ago #2593 ↑ +1

Last evaluated 94 days ago. Current rank #2593. Up 1 spot in the rankings.

Score history

72

Related listings

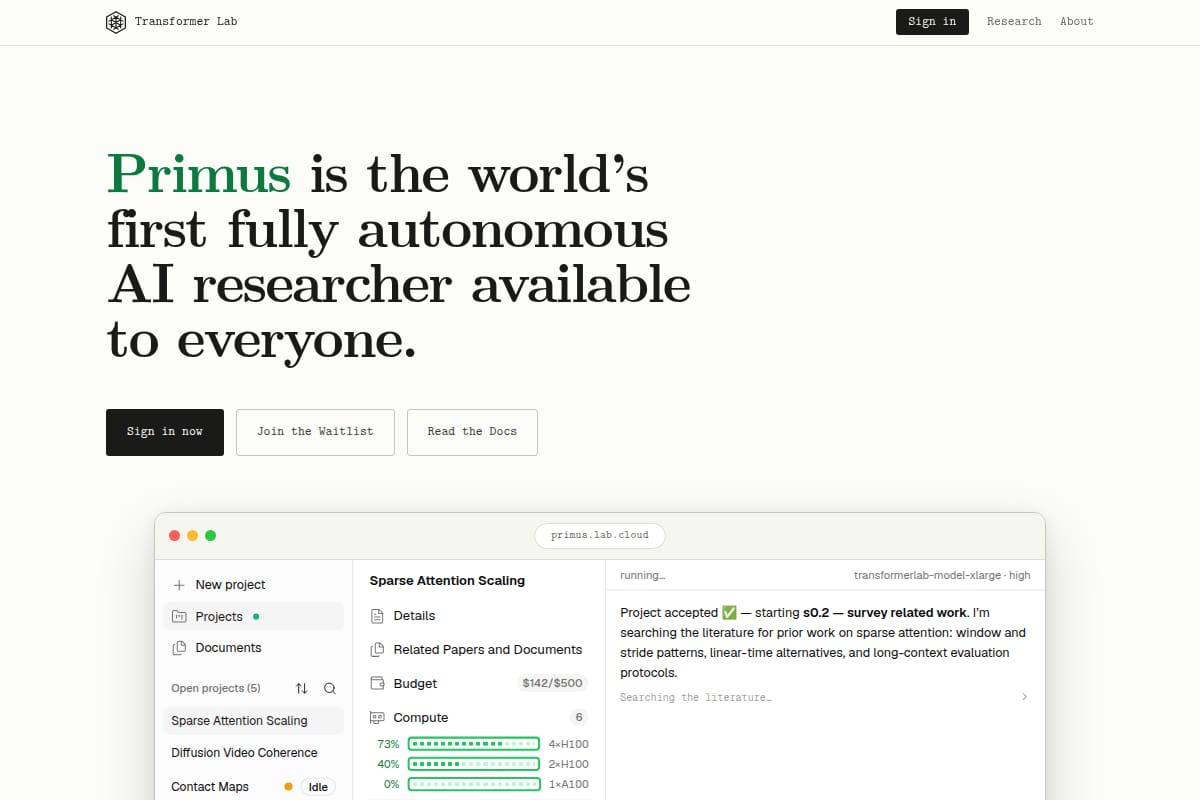
Primus AI Researcher – Free screenshot

Research / Knowledge Work

Primus is an autonomous AI researcher that hypothesizes, reads papers, writes code, runs experiments on compute, and drafts research papers. The page shows example tasks, published-paper claims, waitlist access, and positioning for ML research workflows.

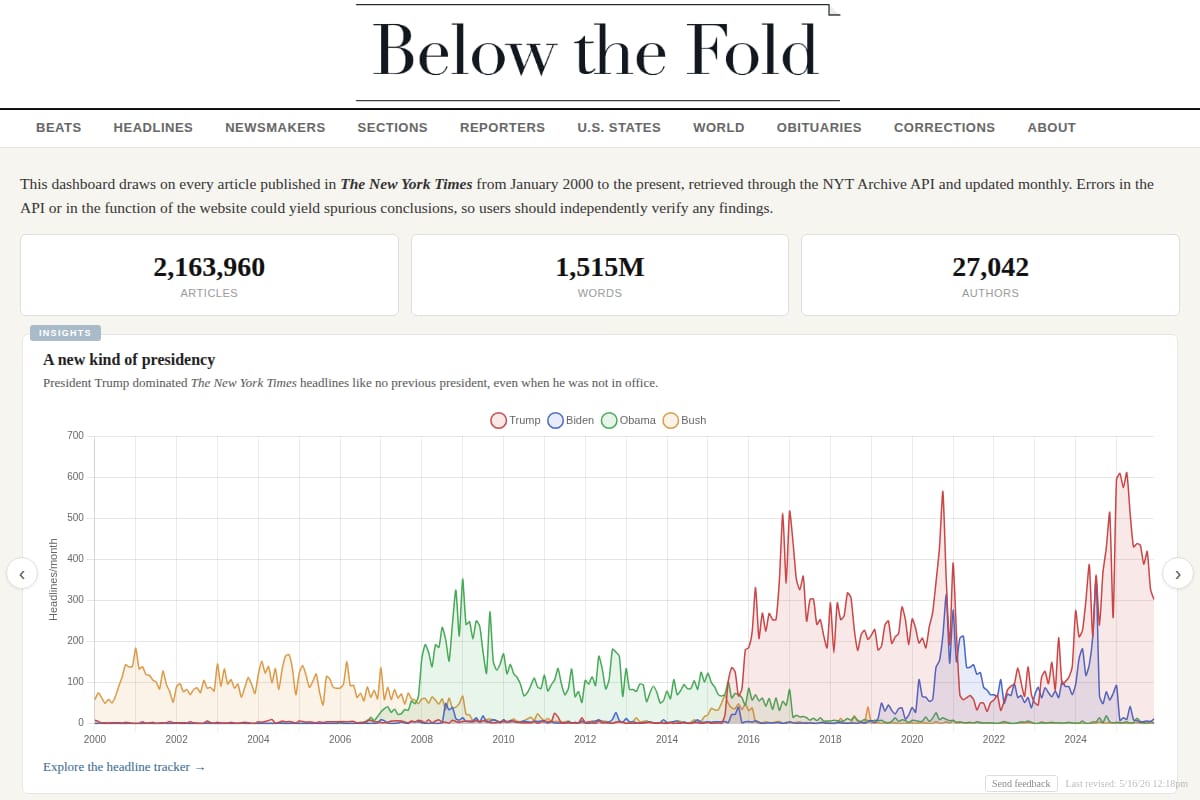
Below the Fold — A New York Times X-Ray Dashboard screenshot

Research / Data Visualization

An interactive dashboard that analyzes New York Times coverage since 2000 using the NYT Archive API, with views for reporters, beats, sections, subjects, geography, obituaries, and corrections.

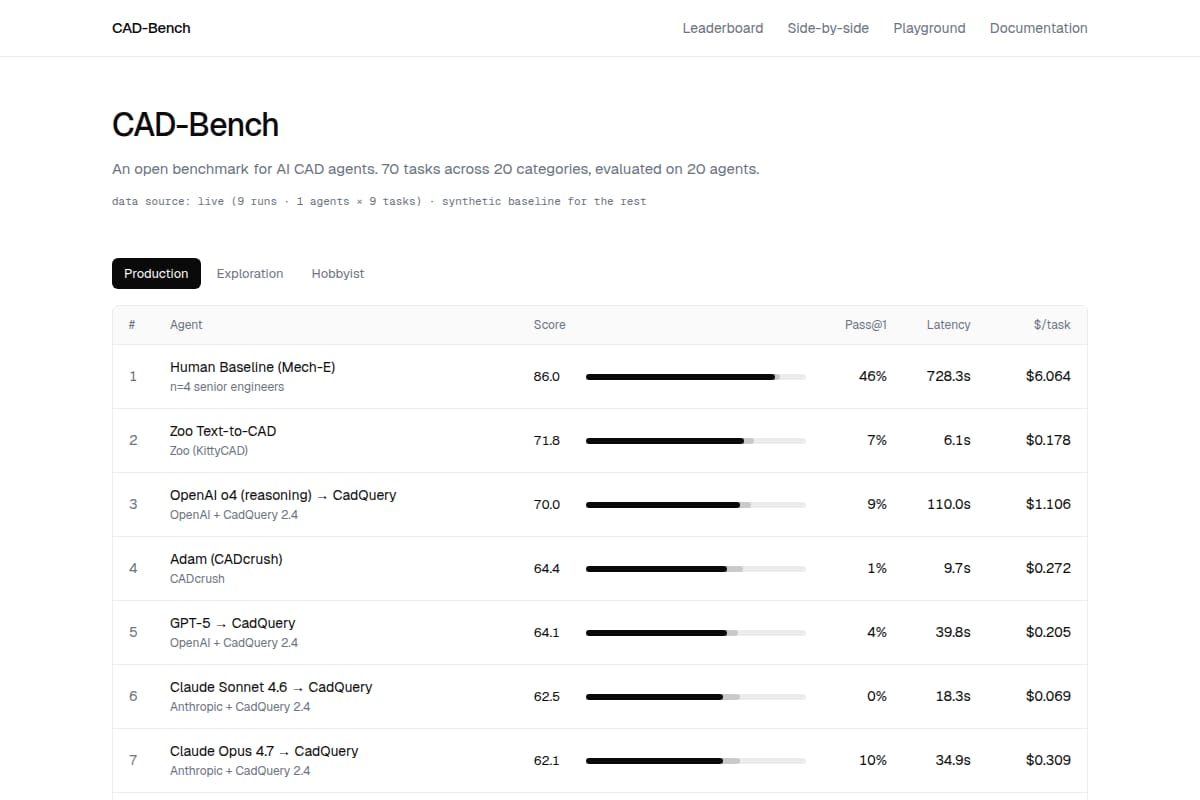
CAD-Bench screenshot
#440 CAD-Bench
88

Research / Knowledge Work

An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition.