
AgentDish directory
benchmark
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#22
↓ -3
gemma4.c
A pure C runtime for Gemma 4 E2B CPU inference, with export, benchmarking, and numerical validation tools included. |
Developer Tools / Machine Learning / Inference Runtime | 91 | ↓ -3 | 70 days ago | Details |
#47
↓ -2
Agentability
An open public experiment that tests whether AI agents can complete everyday web errands, publishes the full transcripts, and scores 113 sites for agent-readiness. |
AI research & benchmarks / Agentic web usability benchmark | 90 | ↓ -2 | 31 days ago | Details |
|
#190
→ 0
ReactBench
ReactBench is a benchmark for evaluating coding agents on realistic React work, with published scores, cost comparisons, and example tasks focused on production-grade frontend issues. |
Developer Tools / Code Assistant | 89 | → 0 | 114 days ago | Details |
A research article benchmarking bot detection systems against scripted browsers, stealth browsers, and modern AI browsing agents, with comparative results across five detection products. |
Research / Knowledge Work | 88 | ↓ -3 | 17 days ago | Details |
#306
↓ -3
Robot Football League (RFL)
An open robot football league where frontier AI models and open-source club code manage simulated Unitree G1 humanoids in daily matches, with live streams, match logs, and a public engine for teams to join. |
Developer Tools / Code Assistant | 88 | ↓ -3 | 73 days ago | Details |
#365
↓ -3
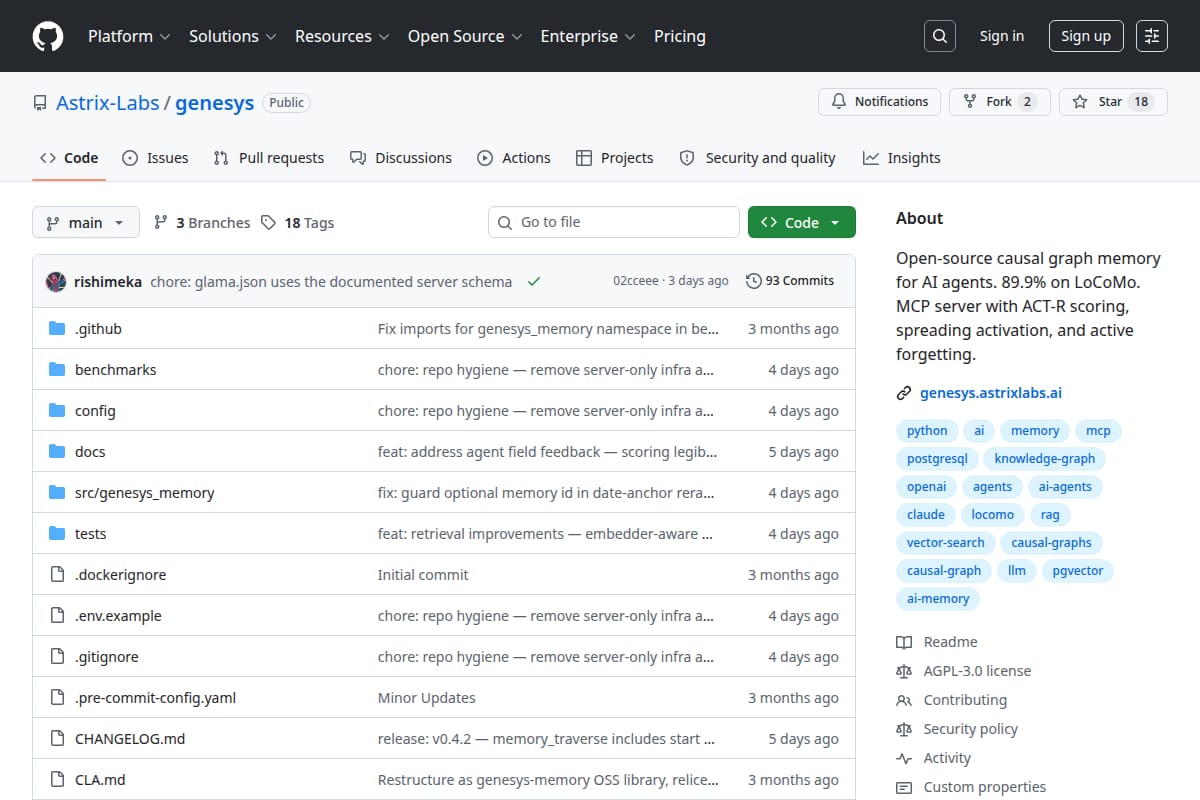
Genesys
Open-source causal-graph memory for AI agents with MCP support, scoring, active forgetting, and benchmark results published in the repo. |
AI Development / Memory / Agent Infrastructure | 88 | ↓ -3 | 108 days ago | Details |
#440
↓ -3
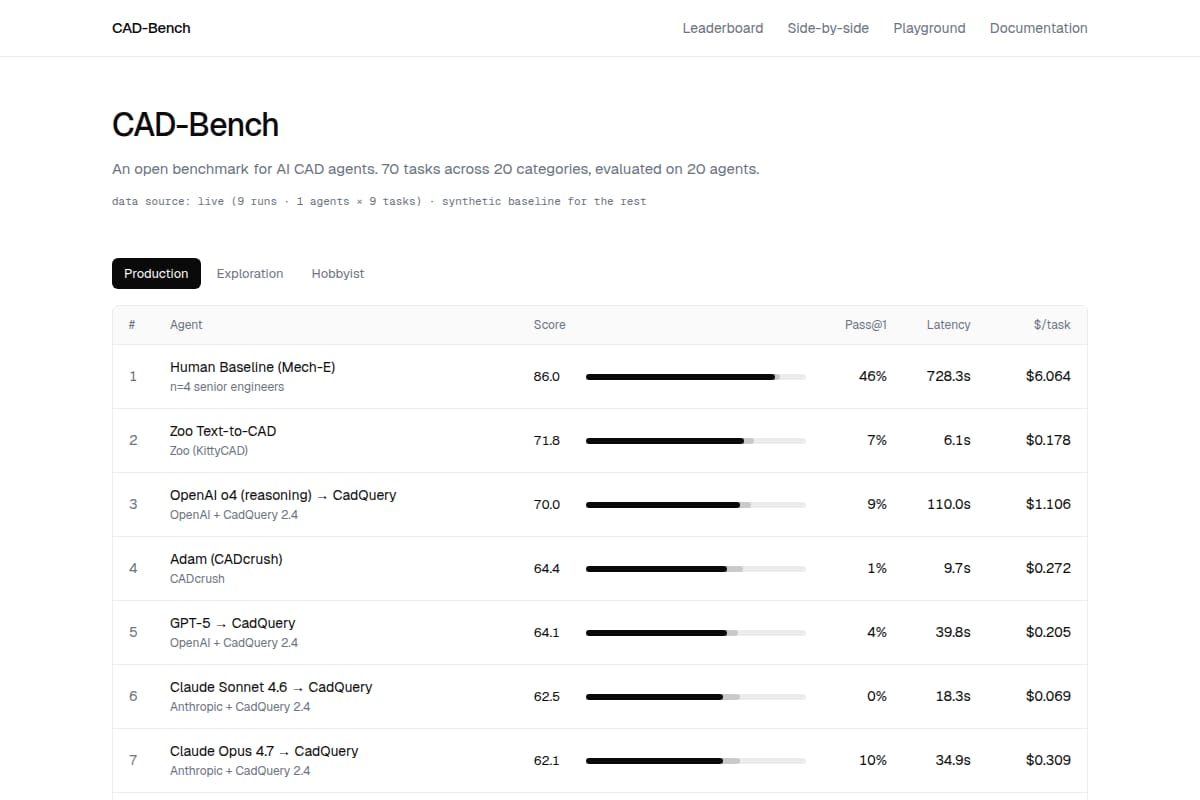
CAD-Bench
An open benchmark and leaderboard for AI CAD agents, with 308 prompts across 20 categories and layered scoring for geometry, engineering, manufacturability, and cognition. |
Research / Knowledge Work | 88 | ↓ -3 | 182 days ago | Details |
#614
↑ +2
smelt
Smelt is an open-source terminal coding agent with a Rust core and Lua plugins, aimed at developers who want a fast, customizable command-line workflow. The page shows install steps, plugin support, vim mode, themes, and benchmark claims comparing memory and speed against other agents. |
Developer Tools / Coding Agents | 86 | ↑ +2 | 11 days ago | Details |
#649
↑ +2
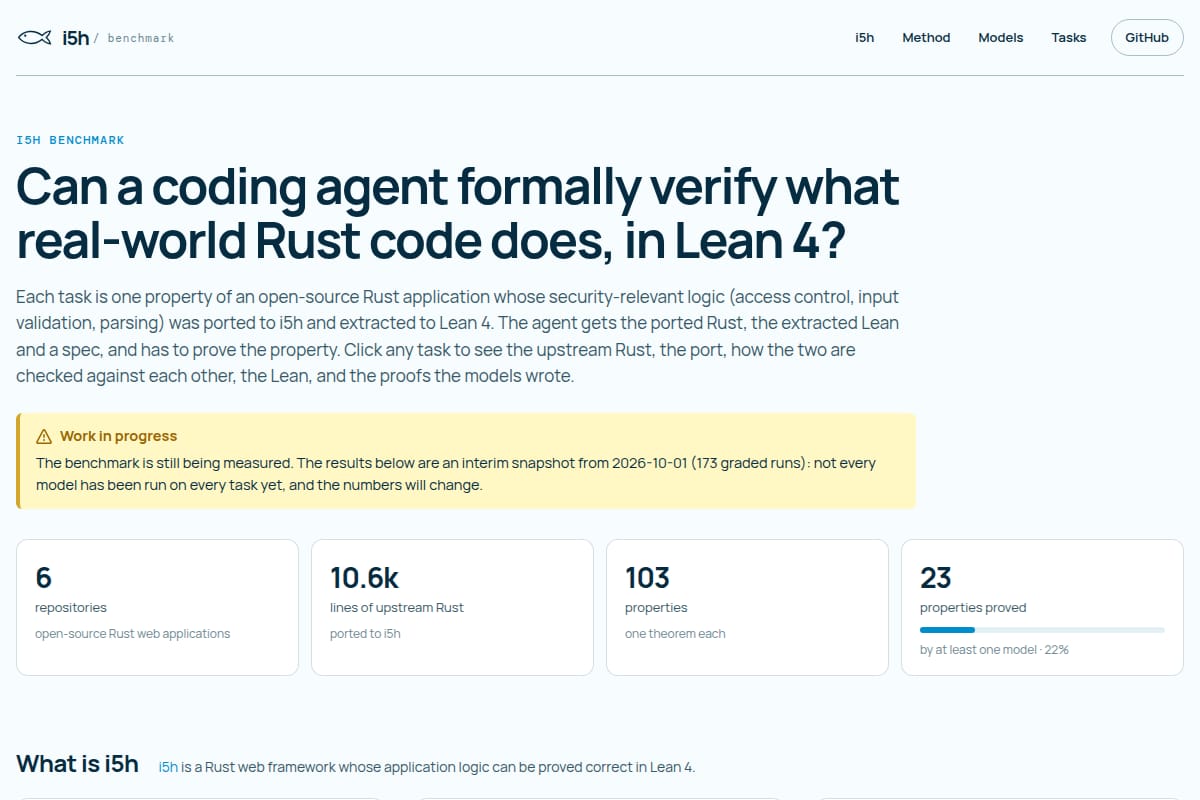
i5h Benchmark
A benchmark for coding agents that tests whether they can formally verify properties of real-world Rust web apps in Lean 4. It includes upstream code, i5h ports, extracted Lean models, proof attempts, and task-by-task results. |
Developer Tools / Code Assistant | 86 | ↑ +2 | 37 days ago | Details |
A Bito research page comparing 29 AI coding models across 60 real engineering tasks, with both quality and cost measured together. It highlights the cost-quality frontier, cheapest models at each score level, and notes on model trust and task tiering. |
AI Research / Benchmarks | 86 | ↑ +2 | 39 days ago | Details |
#667
↑ +2
AI Gateway Models & Pricing
A benchmark page that aggregates public model lists from AI gateways into one matrix, showing which gateways offer each model and their per-million-token pricing. |
Developer Tools / Benchmarking | 86 | ↑ +2 | 49 days ago | Details |
#708
↑ +2
Modded-NanoGPT
Open-source repository for a NanoGPT training speedrun, focused on getting a 124M model to target loss on 8x H100 GPUs in under 90 seconds. The README includes run commands, Docker instructions, and a detailed list of model and systems optimizations. |
Developer Tools / Machine Learning / Training Optimization | 86 | ↑ +2 | 76 days ago | Details |
|
#796
↑ +2
The Banana Test
A visual benchmark that asks AI coding agents to generate a single-file Three.js animation of a banana plant’s full life cycle, then compares the live results side by side. |
AI Tools / Benchmarking | 86 | ↑ +2 | 123 days ago | Details |
#1063
↓ -6
LLM agents play Pokémon showdown
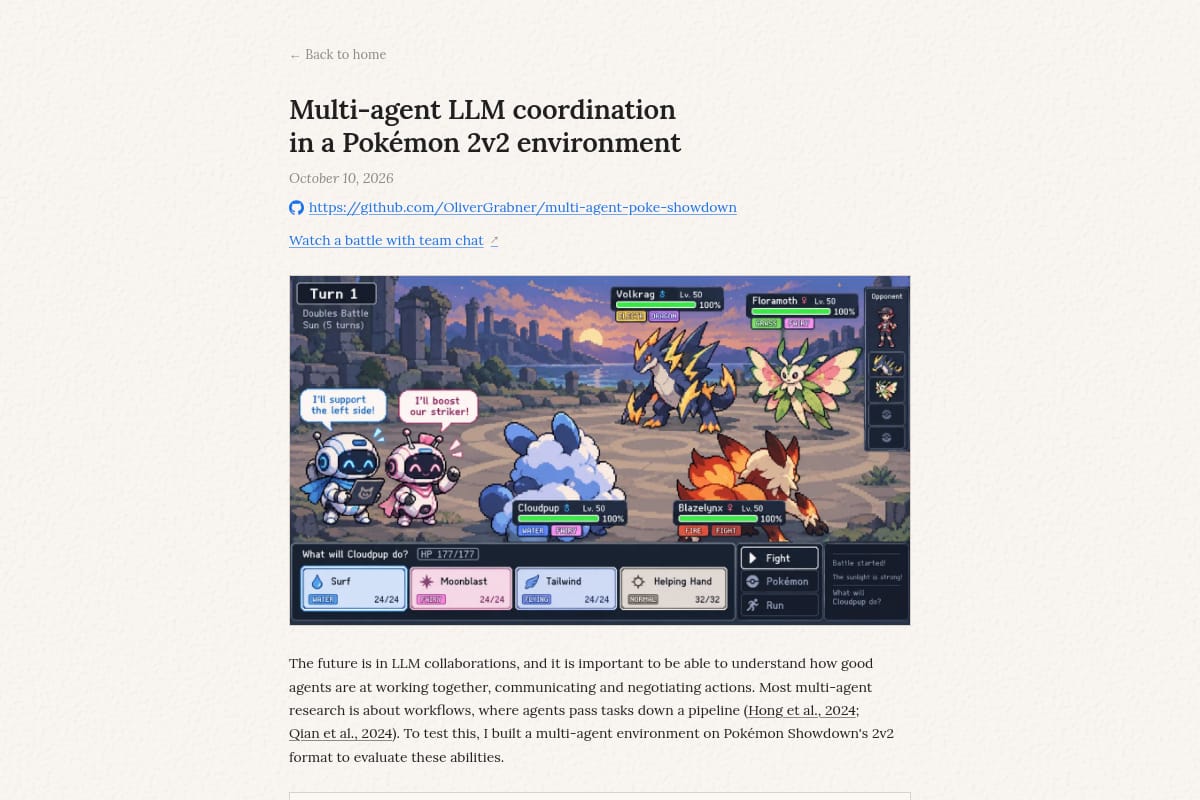
A research project exploring multi-agent LLM coordination in Pokémon Showdown. It compares talk modes, reports win rates and token costs, and frames the environment as a benchmark for studying collaboration between agents. |
Research / Knowledge Work | 84 | ↓ -6 | 16 days ago | Details |
#1120
↓ -6
Jev vs. LLMs on 770 AITA posts
A GitHub repo benchmarking TypeSafe’s Jev against Sonnet, GPT-5 nano, and local models on 770 Reddit AITA verdicts, with Brier scores, latency, and cost comparisons. |
AI benchmark / LLM Evaluation | 84 | ↓ -6 | 44 days ago | Details |
#1155
↓ -6
ObserverBench
ObserverBench is an interactive benchmark and guided demo for testing whether internal AI monitoring methods help make safer decisions, not just better predictions. It includes real-model results, benchmark tasks, and a no-login walkthrough showing how warning scores affect review and harm that slips through. |
Developer Tools / AI Evaluation | 84 | ↓ -6 | 57 days ago | Details |
#1180
↓ -6
Agentic Determinism Index
Open-source harness for measuring how consistently hosted LLM APIs return the same output across repeated runs and over time, with raw transcripts, scoring, and a static leaderboard generator. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 67 days ago | Details |
#1182
↓ -6
Preseason
Open-source benchmark that measures which developer tools LLMs recommend when asked to build real web apps. It runs fixed prompts against a panel of models, parses the tool recommendations, and publishes rankings and head-to-head comparisons. |
Developer Tools / AI Benchmarking | 84 | ↓ -6 | 68 days ago | Details |
#1215
↓ -6
Agent Memory Leaderboard
Public benchmark for comparing agent memory systems, with separate textual and coding tracks, submission flow, documentation, and API guidance. |
Developer Tools / Benchmark | 84 | ↓ -6 | 86 days ago | Details |
#1218
↓ -6
LLM-Tests
An open-source benchmark for testing whether LLMs can follow long arithmetic derivations without using tools. It compares models on recall-proof inputs, logs digit accuracy, and reports results across multiple endpoints and model families. |
Developer Tools / Code Assistant | 84 | ↓ -6 | 87 days ago | Details |
#1392
↓ -6
DeepSWE
DeepSWE is a benchmark for measuring frontier coding agents on original, long-horizon software engineering tasks. The page shows a leaderboard, methodology overview, task examples, and a full blog explaining the benchmark design and results. |
Developer Tools / AI Benchmarking | 84 | ↓ -6 | 163 days ago | Details |
#1478
↓ -3
sudo L7
A benchmark for testing whether coding agents can show staff-level engineering judgment, not just produce correct code. |
AI benchmark / Coding benchmark | 83 | ↓ -3 | 18 days ago | Details |
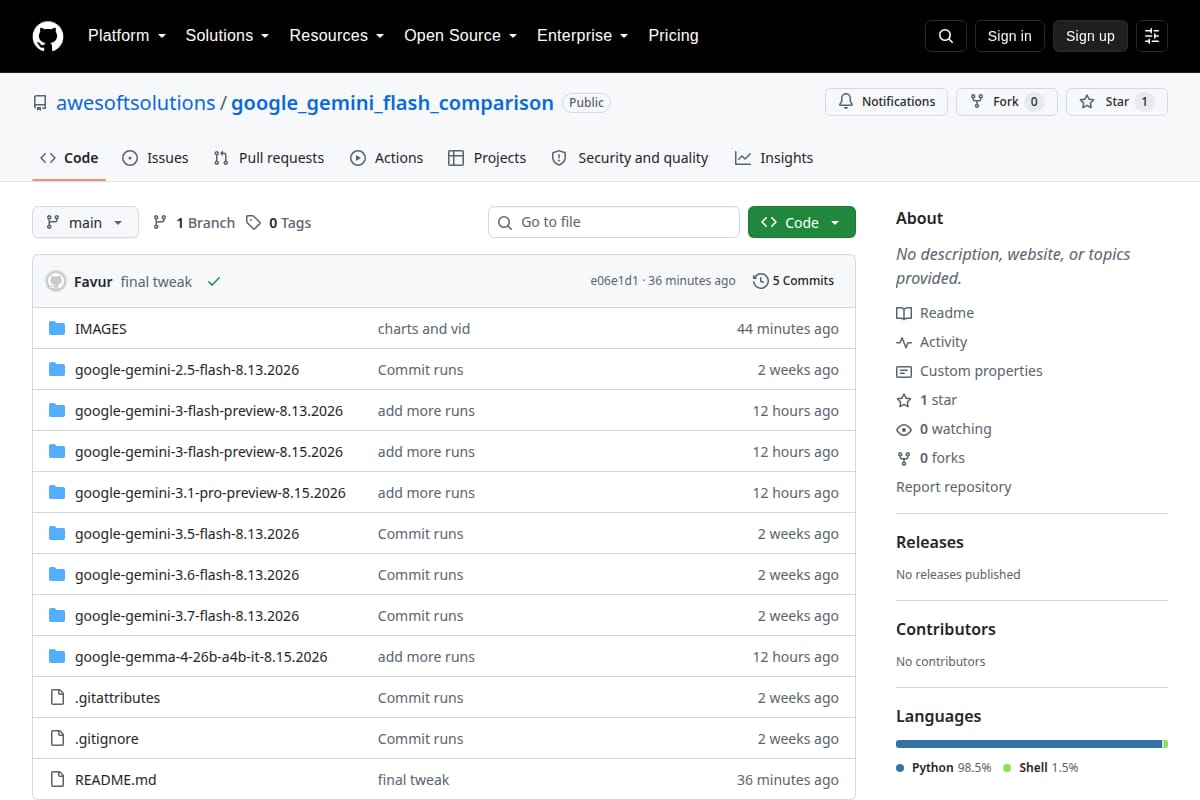
A GitHub repository that publishes a week of controlled runs comparing seven Google models on the same software task, with transcripts, telemetry, screenshots, and scored benchmark artifacts. |
AI Development / Benchmarking | 83 | ↓ -3 | 75 days ago | Details |

A black-box benchmark report on how AI-generated tests detect functional bugs in live APIs across 20 scenarios and 7 systems. |
Developer Tools / Code Assistant | 83 | ↓ -3 | 156 days ago | Details |