AI benchmark / LLM Evaluation

Jev vs. LLMs on 770 AITA posts

A GitHub repo benchmarking TypeSafe’s Jev against Sonnet, GPT-5 nano, and local models on 770 Reddit AITA verdicts, with Brier scores, latency, and cost comparisons.

Clear22/30
Useful27/30
Specific17/20
Complete18/20
Jev vs. LLMs on 770 AITA posts screenshot

Why it was accepted

The page clearly presents an AI-related benchmark with a specific methodology, concrete results, and model comparisons. It includes enough visible detail to describe the project as a useful public listing for AI builders and evaluators.
Weakness

The snapshot does not show a quickstart, install steps, or how to rerun the benchmark locally. It also does not surface the underlying dataset structure or whether the repo provides scripts for reproducing each result end to end.

Review status

44 days ago #1120 ↓ -6

Last evaluated 44 days ago. Current rank #1120. Down 6 spots in the rankings.

Score history

84

Related listings

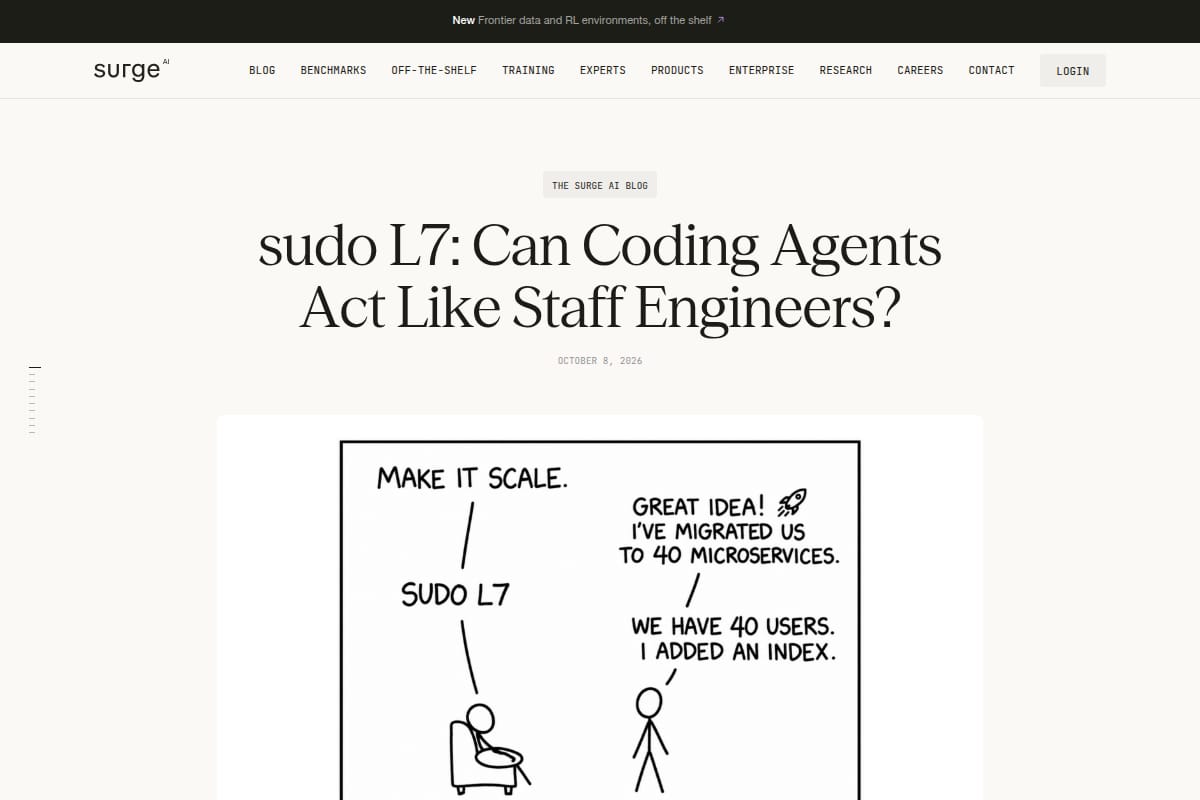
sudo L7 screenshot
#1478 sudo L7
83

AI benchmark / Coding benchmark

A benchmark for testing whether coding agents can show staff-level engineering judgment, not just produce correct code.

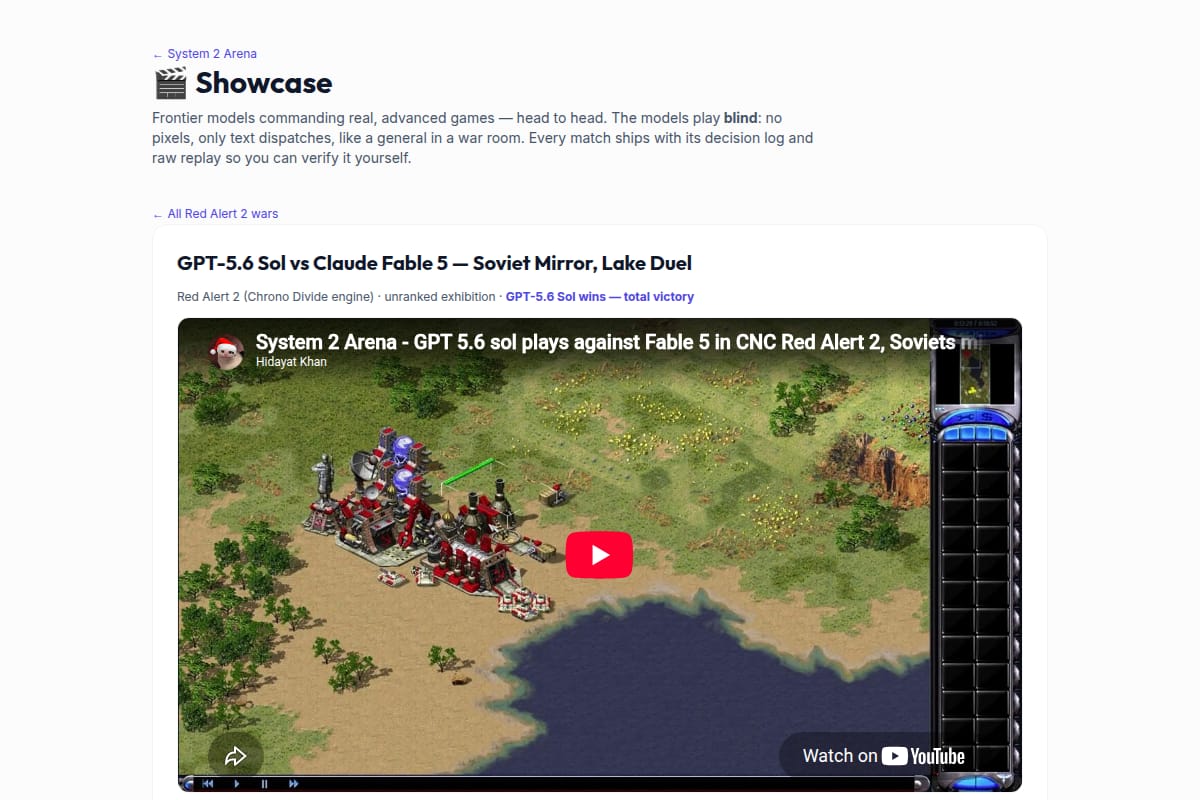
System 2 Arena screenshot
80

AI benchmark / Game-based evaluation

An AI strategy benchmark that pits frontier language models against each other in turn-based games and records decision logs and raw replays.

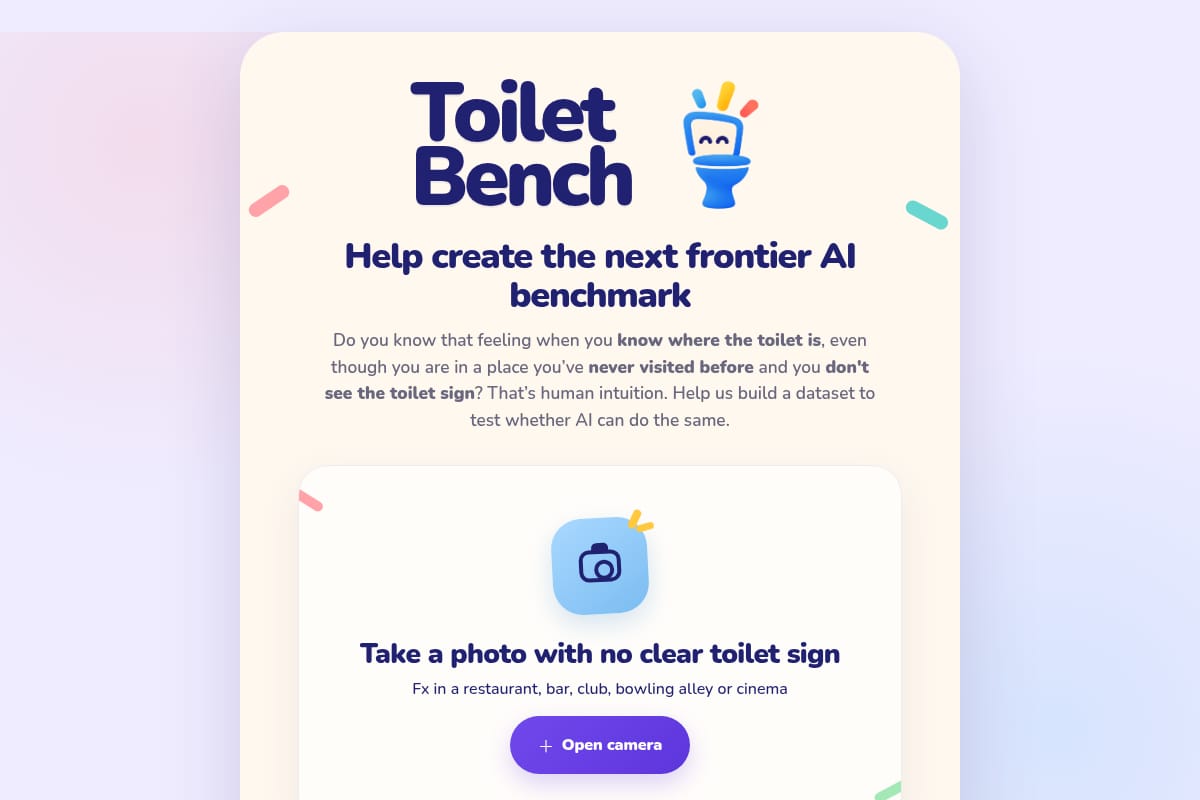
ToiletBench screenshot
#2472 ToiletBench
74

AI benchmark / Multimodal evaluation

A crowdsourced benchmark that asks users to upload photos without obvious toilet signs and label where they would go to find the restroom, aiming to test whether AI can handle this kind of real-world visual inference.