
AgentDish directory
benchmark
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1665
↓ -2
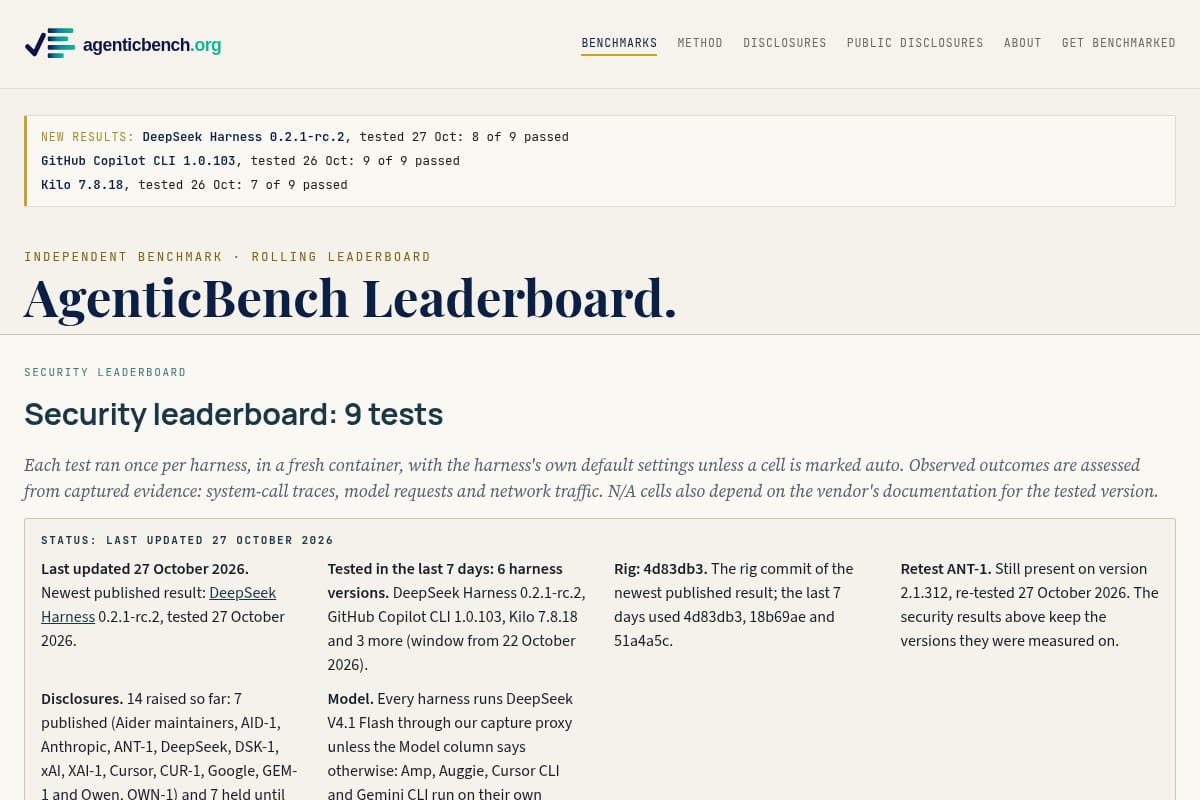
AgenticBench
A public security leaderboard for AI coding agents, showing 9 benchmark tests across multiple harness versions with dates, outcomes, disclosures, and re-test status. |
Developer Tools / AI Security Benchmark | 82 | ↓ -2 | 10 days ago | Details |
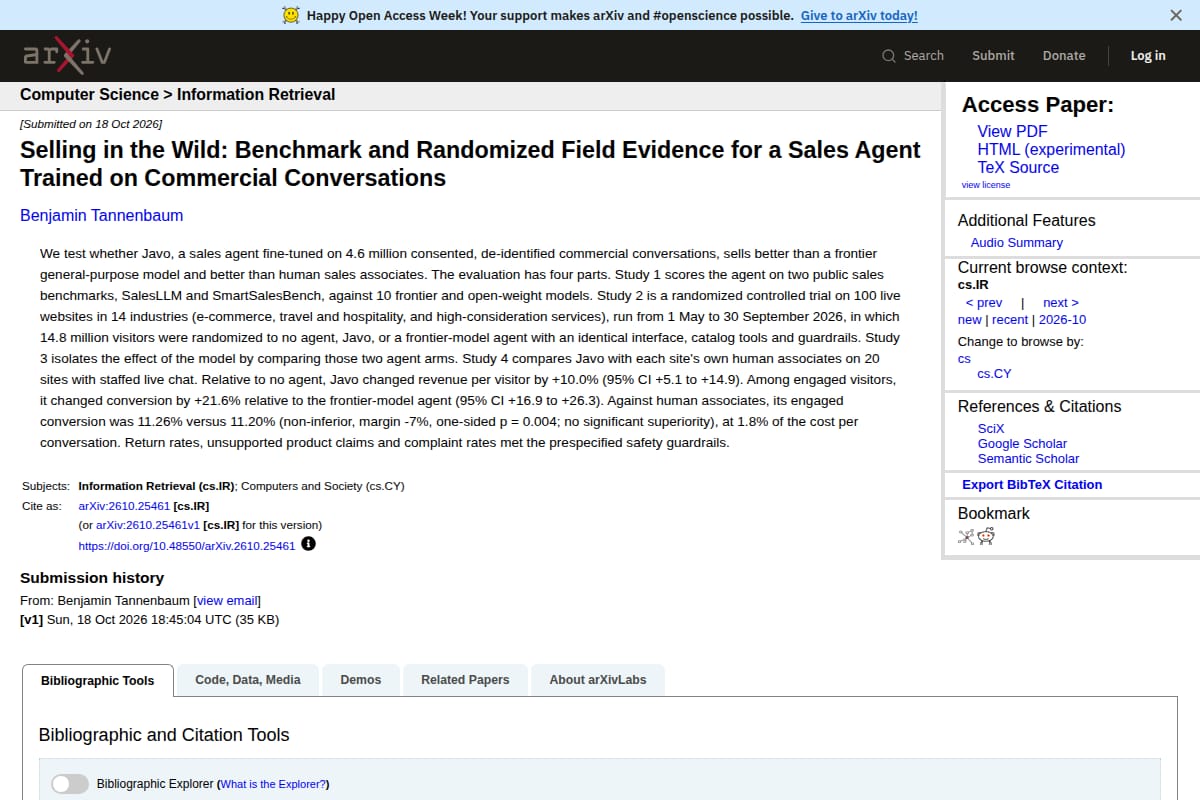
arXiv paper on Javo, a sales agent trained on commercial conversations and evaluated through public benchmarks plus a randomized field trial across 100 live websites. |
Research / AI Agents | 82 | ↓ -2 | 18 days ago | Details |
#1699
↓ -2
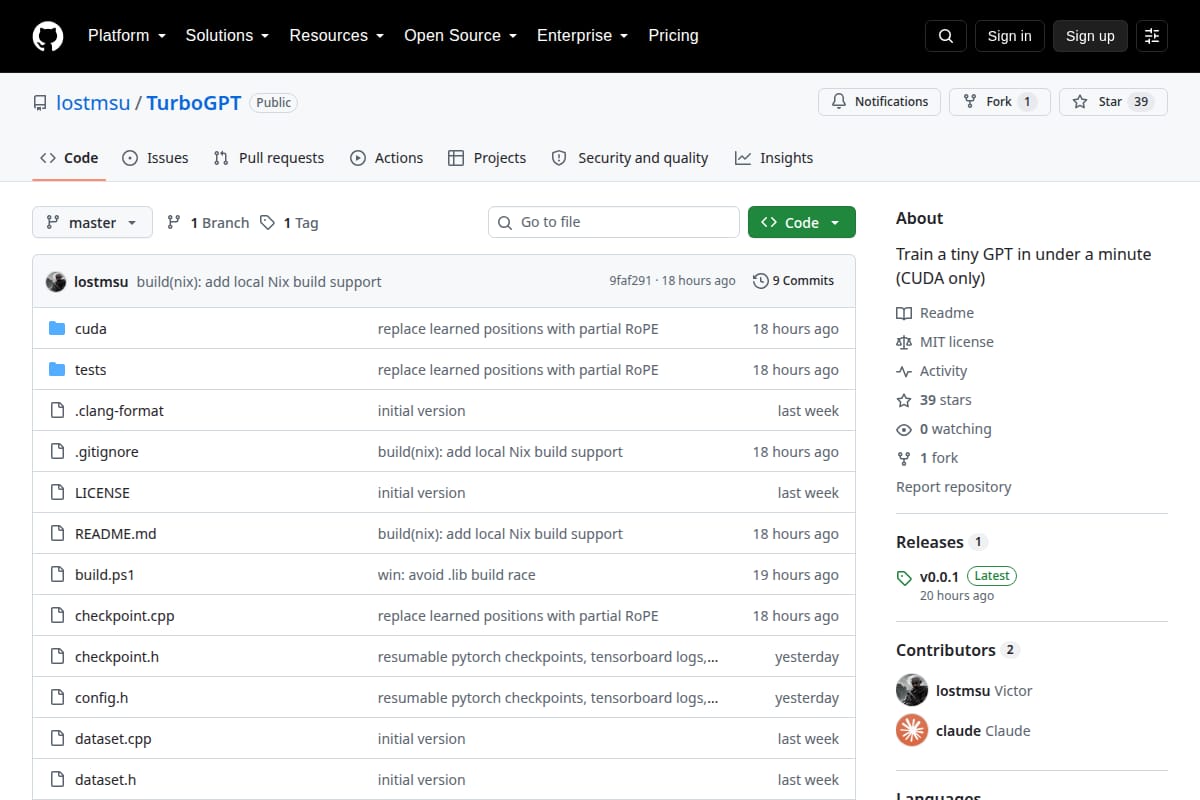
TurboGPT
A CUDA C++ project for training a tiny byte-level GPT quickly, with build, run, checkpoint, logging, and test instructions in the repo README. |
Developer Tools / Machine Learning | 82 | ↓ -2 | 38 days ago | Details |
#1964
↑ +2
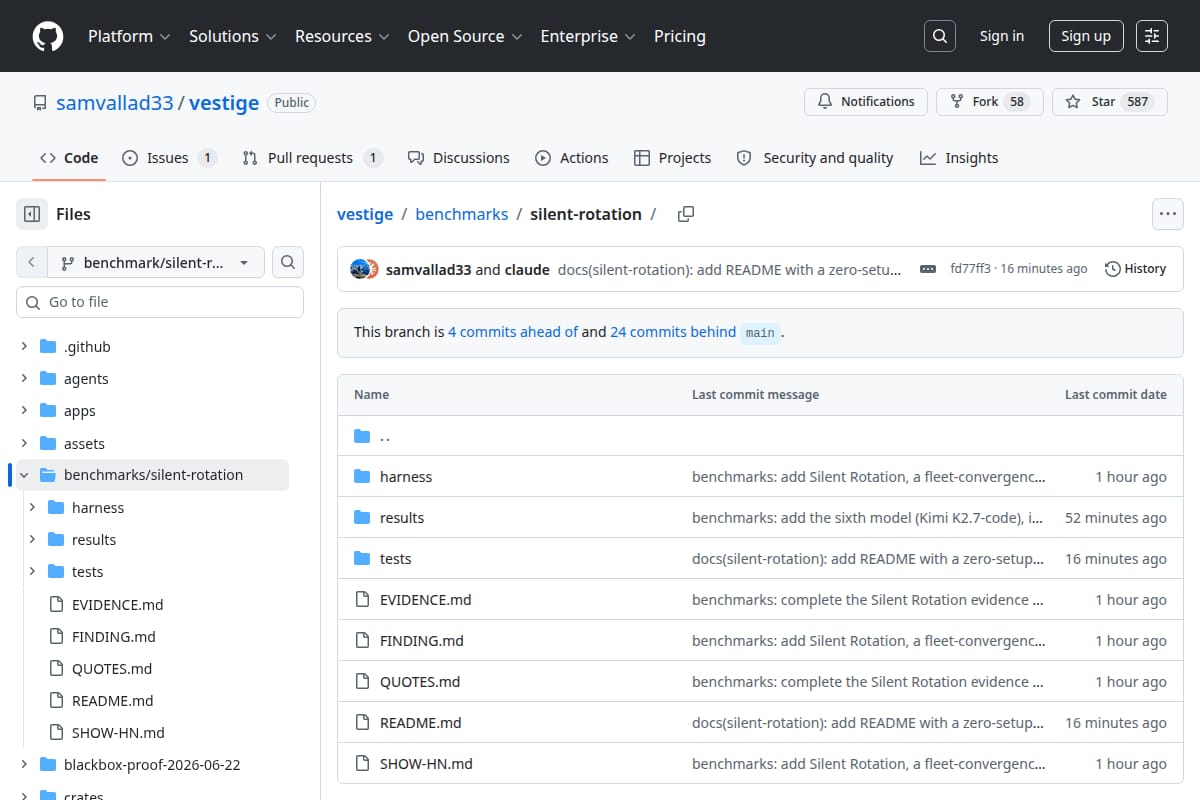
Vestige – Silent Rotation benchmark
A GitHub repo section documenting a benchmark for Vestige, a local-first Rust MCP memory layer for multi-agent coding fleets. The page explains the benchmark setup, what is being measured, how to reproduce the main claim, and where to find transcripts, evidence, and harness code. |
Developer Tools / AI / ML Infrastructure | 81 | ↑ +2 | 109 days ago | Details |

A workbench report comparing MiniMax M3 and GLM 5.2 on autonomous coding tasks, with scored results, latency and cost data, task-type breakdowns, and examples of where each model performed better. |
Developer Tools / Code Assistant | 81 | ↑ +2 | 140 days ago | Details |
#2051
↓ -1
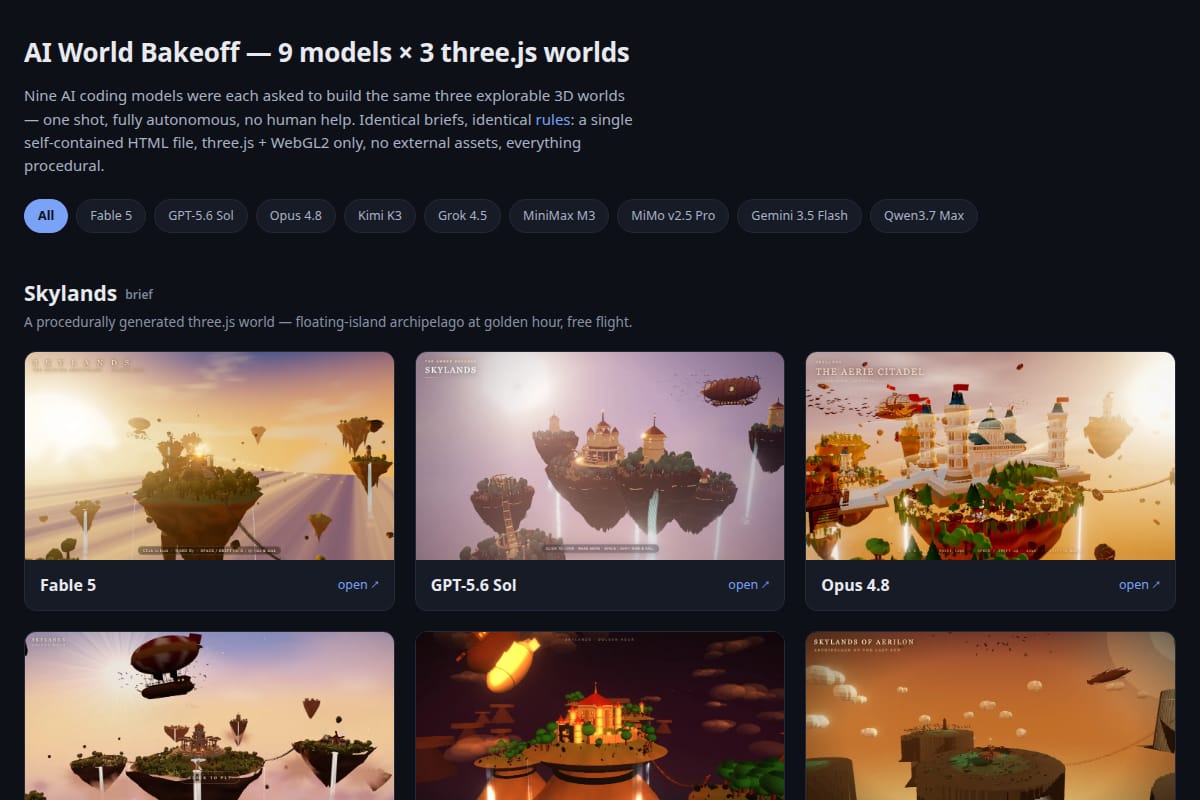
AI World Bakeoff
A showcase of 27 explorable Three.js worlds built autonomously by 9 coding models from the same brief. |
Design / Creative Tools | 80 | ↓ -1 | 109 days ago | Details |
#2097
↑ +2
rcaptcha
A reverse CAPTCHA site that gives short timed tasks for LLMs and agents, with an MCP endpoint, machine-readable docs, challenge submission, certificates, and a leaderboard. |
AI Tool / Agent Challenge / Verification | 79 | ↑ +2 | 18 days ago | Details |
A GitHub repo for a geospatial benchmark that tests how well six LLMs can classify points in San Francisco from memory and compares results against OpenStreetMap. It includes code, answers, answer keys, costs, and figures for reproducing the analysis. |
Developer Tools / Code Assistant | 79 | ↑ +2 | 19 days ago | Details |
#2101
↑ +2
StarSkirmish Hillclimb
A benchmark page for frontier models racing to write a StarCraft: Brood War bot in C++ using BWAPI and OpenBW, climbing tiers of increasingly strong Protoss opponents. |
AI Tools / Game AI | 79 | ↑ +2 | 35 days ago | Details |
#2212
↑ +6
Awesome Bare-Metal AI
A curated GitHub list and benchmark leaderboard for ultra-lightweight, zero-dependency AI engines in C/C++/Rust/Assembly, covering local LLMs, vector search, memory, GEMM, and agent tooling. |
Developer Tools / AI Infrastructure | 78 | ↑ +6 | 54 days ago | Details |
#2225
↑ +6
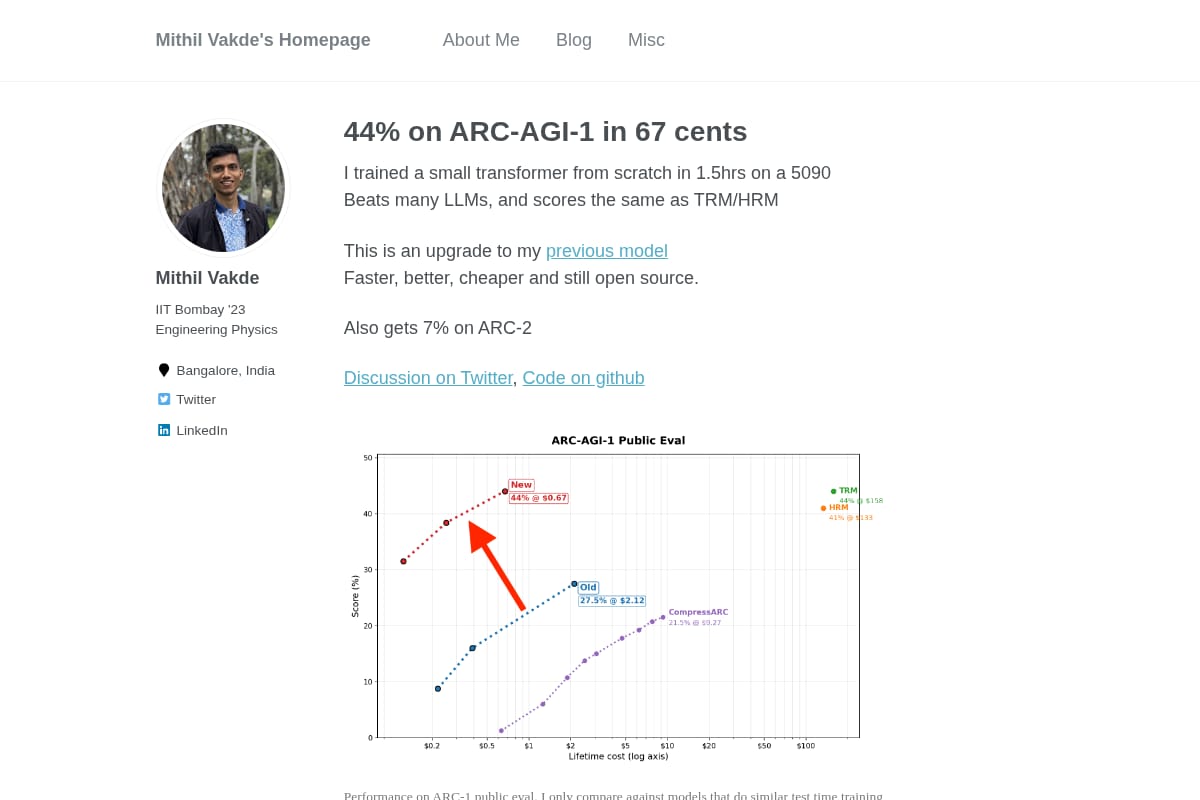
44% on ARC-AGI-1 in 67 cents
A research blog post describing an open-source small transformer trained from scratch to reach 44% on ARC-AGI-1 at very low cost, with architecture notes, ablations, and pointers to code. |
Research / ML Experiment / Benchmark Result | 78 | ↑ +6 | 66 days ago | Details |
A Topos case study showing how a guided refactor of a synthetic healthcare claims engine reduced token usage, wall time, and estimated cost for later Gemini feature sessions. |
Developer Tools / Code Assistant | 78 | ↑ +6 | 134 days ago | Details |
#2344
→ 0
agent-memory-leaderboard
Public evaluation code for an Agent Memory Leaderboard, including answer-generation and scoring contracts for comparing LLM agent memory systems. |
Developer Tool / AI Evaluation / Benchmarking | 77 | → 0 | 97 days ago | Details |
#2392
↓ -1
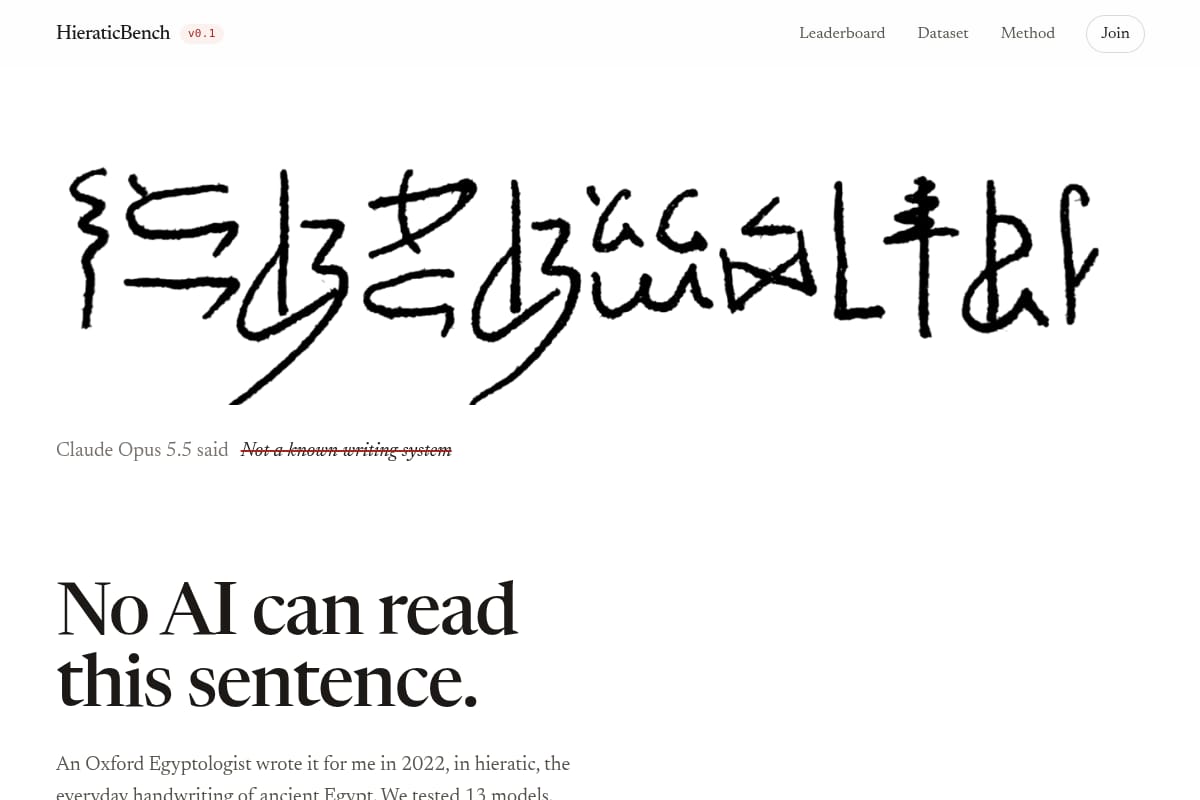
HieraticBench
A benchmark site testing whether AI models can recognize and read hieratic, the handwriting of ancient Egypt. The page shows model answers, leaderboard context, and the task framing around identifying, transliterating, and translating the script. |
AI Tools / Benchmarks & Evaluation | 76 | ↓ -1 | 31 days ago | Details |
#2472
↓ -1
ToiletBench
A crowdsourced benchmark that asks users to upload photos without obvious toilet signs and label where they would go to find the restroom, aiming to test whether AI can handle this kind of real-world visual inference. |
AI benchmark / Multimodal evaluation | 74 | ↓ -1 | 12 days ago | Details |
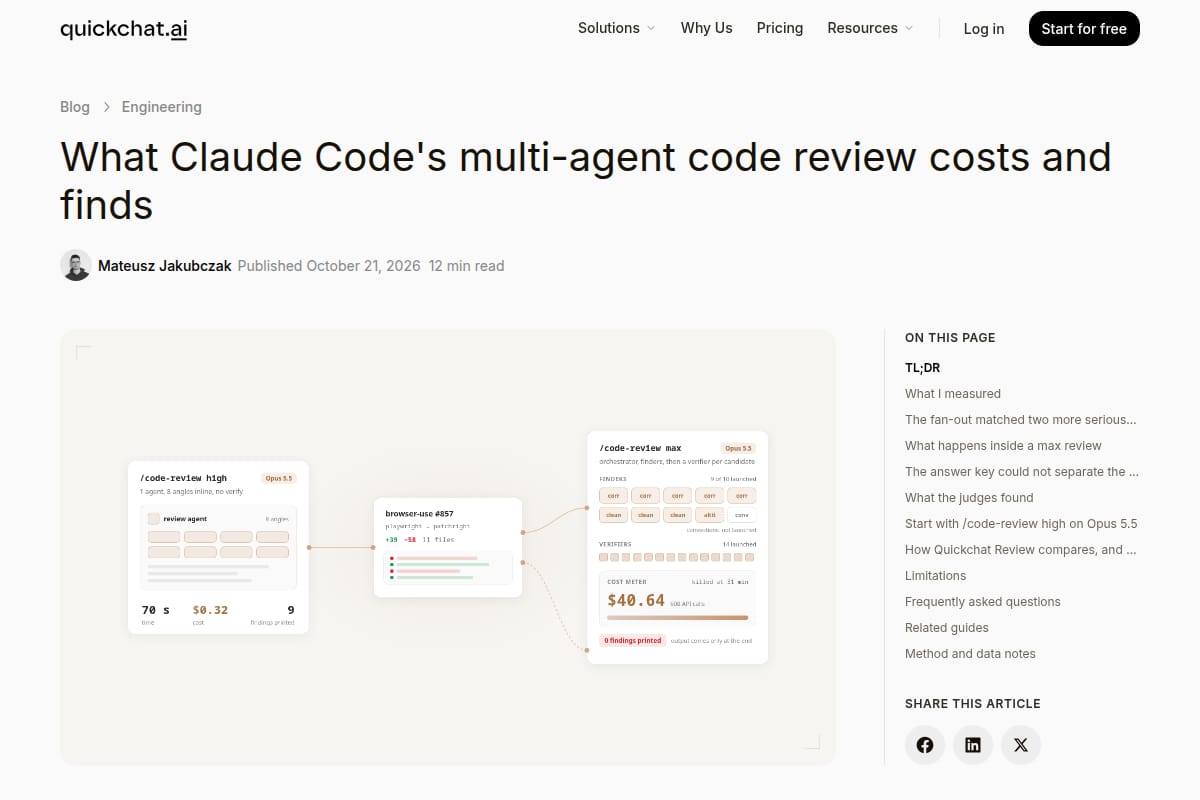
A detailed benchmark-style article comparing Claude Code’s single-agent and multi-agent /code-review modes on hard pull requests, with measured cost, latency, and issue-detection results, plus a comparison to Quickchat Review. |
Writing / Copywriting | 74 | ↓ -1 | 17 days ago | Details |
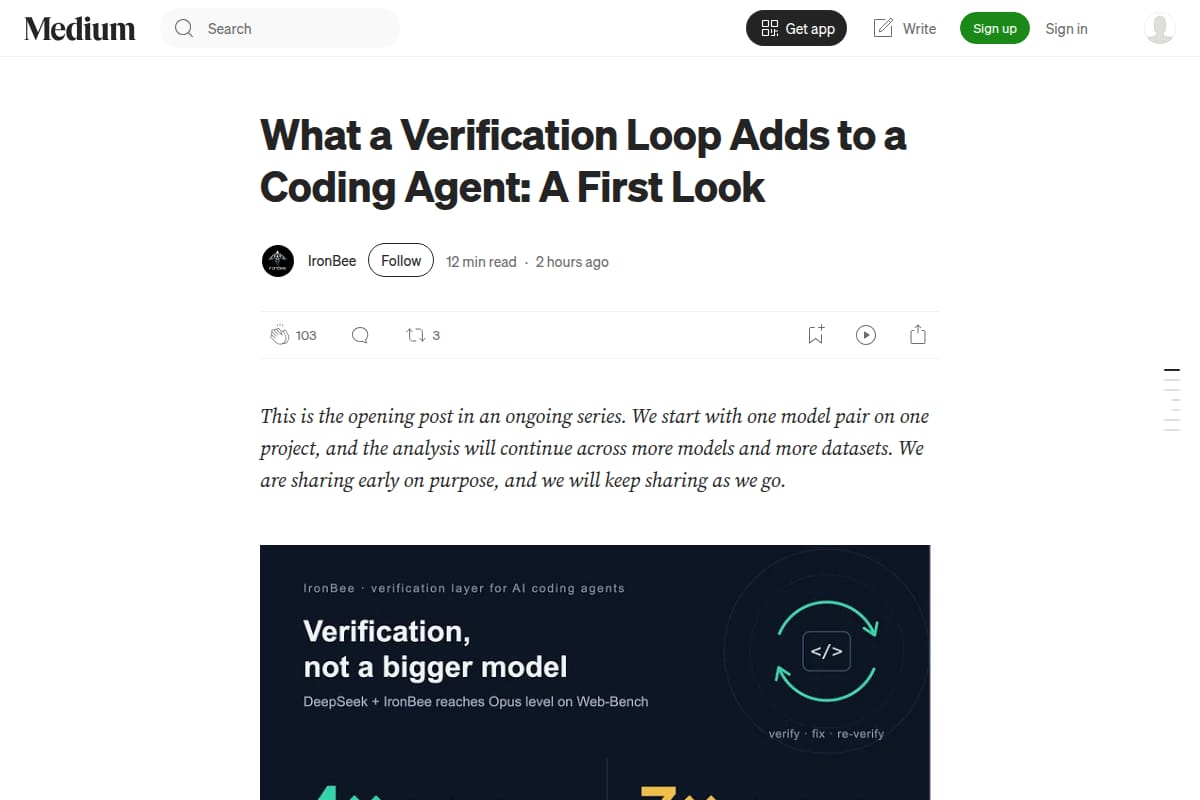
An in-depth Medium post from IronBee about how a verification loop affects AI coding agents, using Web-Bench and comparing DeepSeek with Claude Opus on a real web app task. |
Developer Tools / Code Assistant | 74 | ↓ -1 | 123 days ago | Details |
#2562
↑ +1
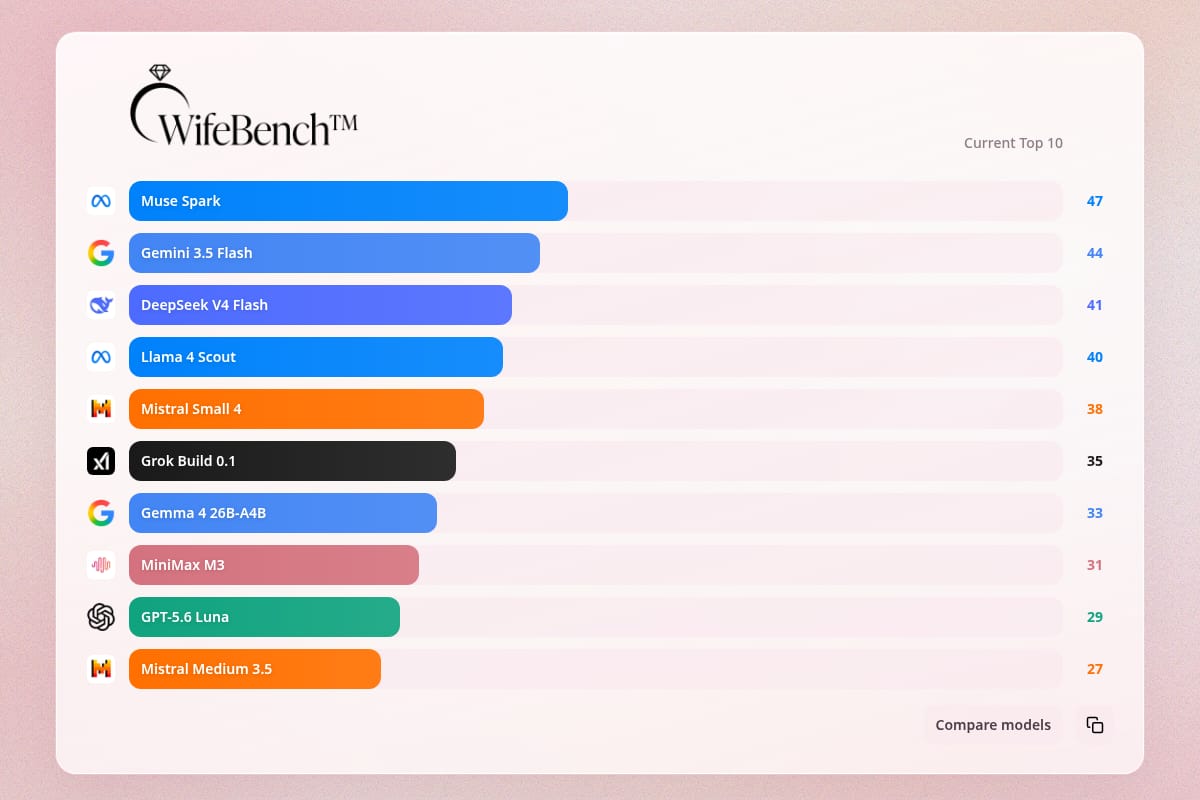
WifeBench
A playful benchmark dashboard that ranks LLMs based on one person's 10-question scoring process. |
Writing / Copywriting | 73 | ↑ +1 | 125 days ago | Details |