
AgentDish directory
evaluation
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1957
↑ +2
iFixAi
Open-source auditing tool for AI agents that checks whether an agent is doing the job it is supposed to do. The repo shows a guided CLI, plugin-based workflows for Claude Code and Codex, and output in JSON, Markdown, and terminal scorecards. |
Developer Tools / Code Assistant | 81 | ↑ +2 | 87 days ago | Details |
#1967
↑ +2
BOUND
BOUND is a deterministic control harness for AI agents. It sits between agent execution and the next decision, using observable evidence to choose ACCEPT, RETRY, REPLAN, or ROLLBACK. |
Developer Tool / AI Agent Framework / Control Harness | 81 | ↑ +2 | 112 days ago | Details |
A GitHub repo for a geospatial benchmark that tests how well six LLMs can classify points in San Francisco from memory and compares results against OpenStreetMap. It includes code, answers, answer keys, costs, and figures for reproducing the analysis. |
Developer Tools / Code Assistant | 79 | ↑ +2 | 19 days ago | Details |
#2136
↑ +2
Marker
Marker is an AI testing and verification platform for voice agents, with a focus on simulation, transcripts, judgments, and versioned evidence across the workflow. |
Developer Tools / AI Testing & Evaluation | 79 | ↑ +2 | 100 days ago | Details |
#2166
↑ +2
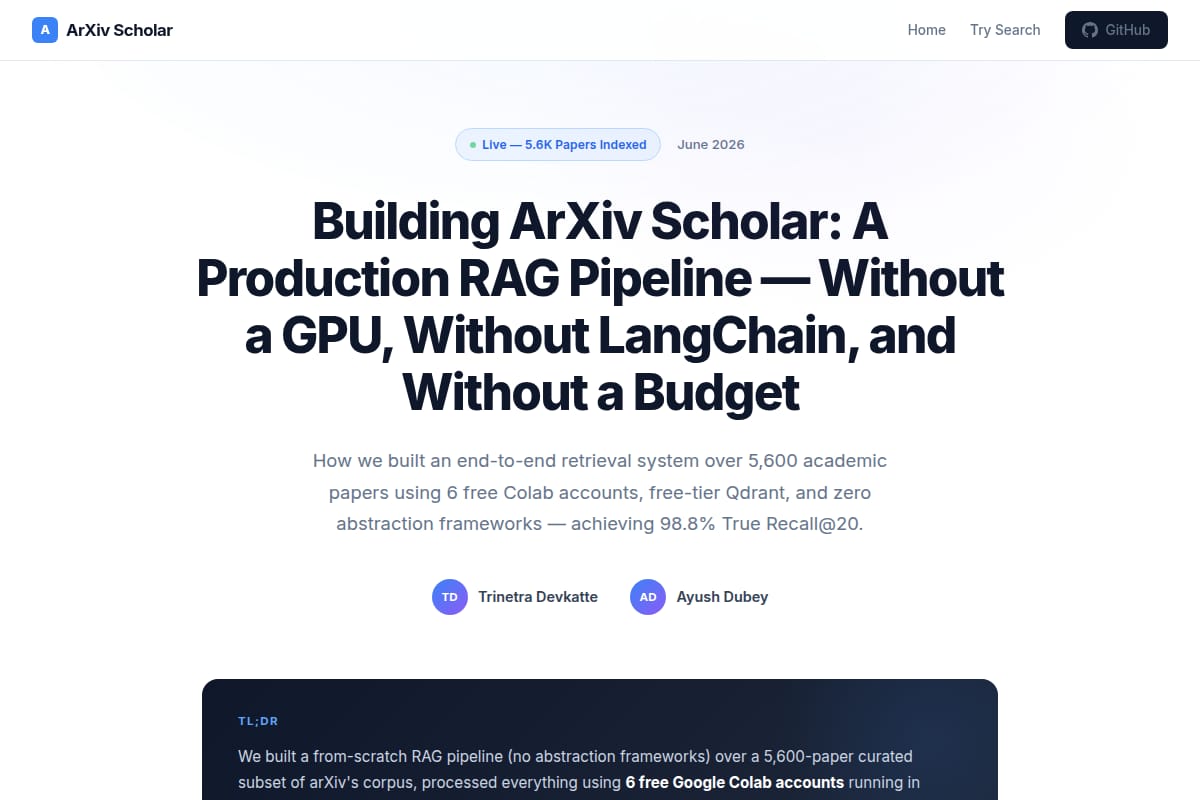
ArXiv Scholar
A zero-budget research search engine and RAG pipeline for 5,600 arXiv papers, built with free Colab processing, Qdrant free tier, and hybrid dense+sparse retrieval. |
AI / Search / RAG / Research search | 79 | ↑ +2 | 144 days ago | Details |
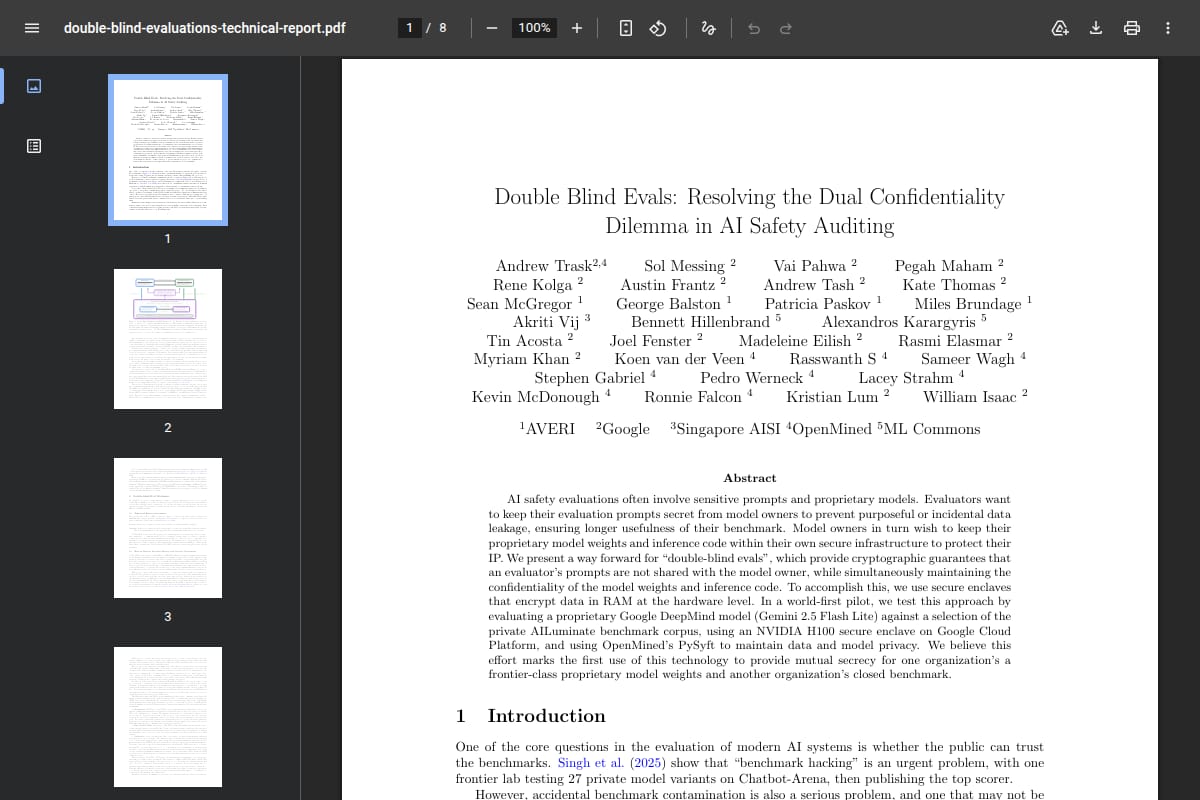
A DeepMind technical report PDF about double-blind AI evaluations and confidentiality issues in AI safety research. |
Research / AI Safety | 78 | ↑ +6 | 66 days ago | Details |
#2239
↑ +6
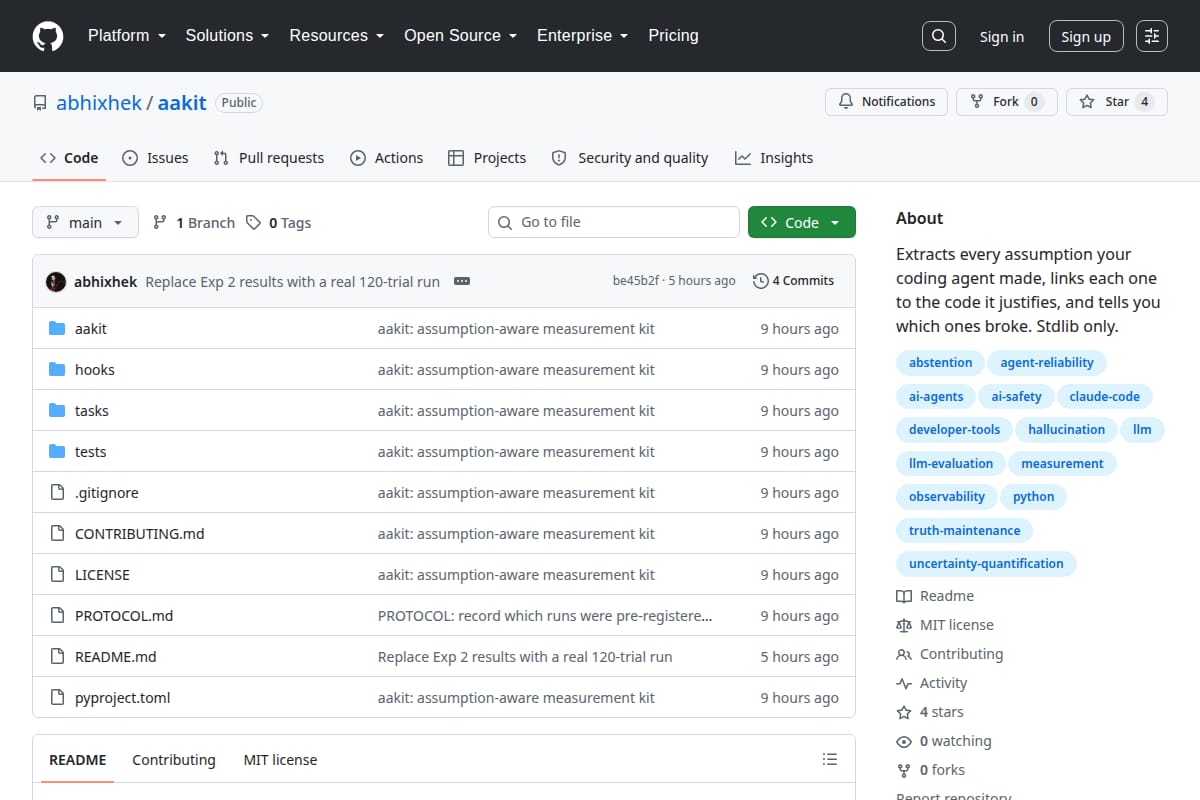
aakit
Aakit is a developer tool for measuring and tracking assumptions made by coding agents, linking each assumption to supporting code and flagging which ones fail. The repo includes a clear explanation of the idea, prior art, and early experiment results. |
Developer Tools / Code Assistant | 78 | ↑ +6 | 87 days ago | Details |
A research page on how censorship and behavior transfer during model distillation, with published models, data, evaluation code, and a benchmark called LineageEval. |
Research / AI Safety / Model Behavior | 78 | ↑ +6 | 99 days ago | Details |
A GitHub example that audits LangChain’s RAG quickstart with retrieval-quality metrics, flags off-topic and out-of-distribution queries, and surfaces ranking and calibration issues with charts and results files. |
Developer Tool / RAG Evaluation | 78 | ↑ +4 | 185 days ago | Details |
A Supabase blog post about testing documentation with an eval, finding agent-driven RLS setup failures, and revising the guide to work better for coding agents. |
Writing / Copywriting | 77 | → 0 | 60 days ago | Details |
#2344
→ 0
agent-memory-leaderboard
Public evaluation code for an Agent Memory Leaderboard, including answer-generation and scoring contracts for comparing LLM agent memory systems. |
Developer Tool / AI Evaluation / Benchmarking | 77 | → 0 | 97 days ago | Details |
#2457
→ 0
Clusy
Clusy is an agent-native notebook platform for ML and data science work in the cloud. The page says it can source data, inspect it, choose architecture and compute, and run end-to-end workflows, with a demo showing a finetuning task and follow-up work queued while the notebook runs. |
Research / Knowledge Work | 75 | → 0 | 129 days ago | Details |
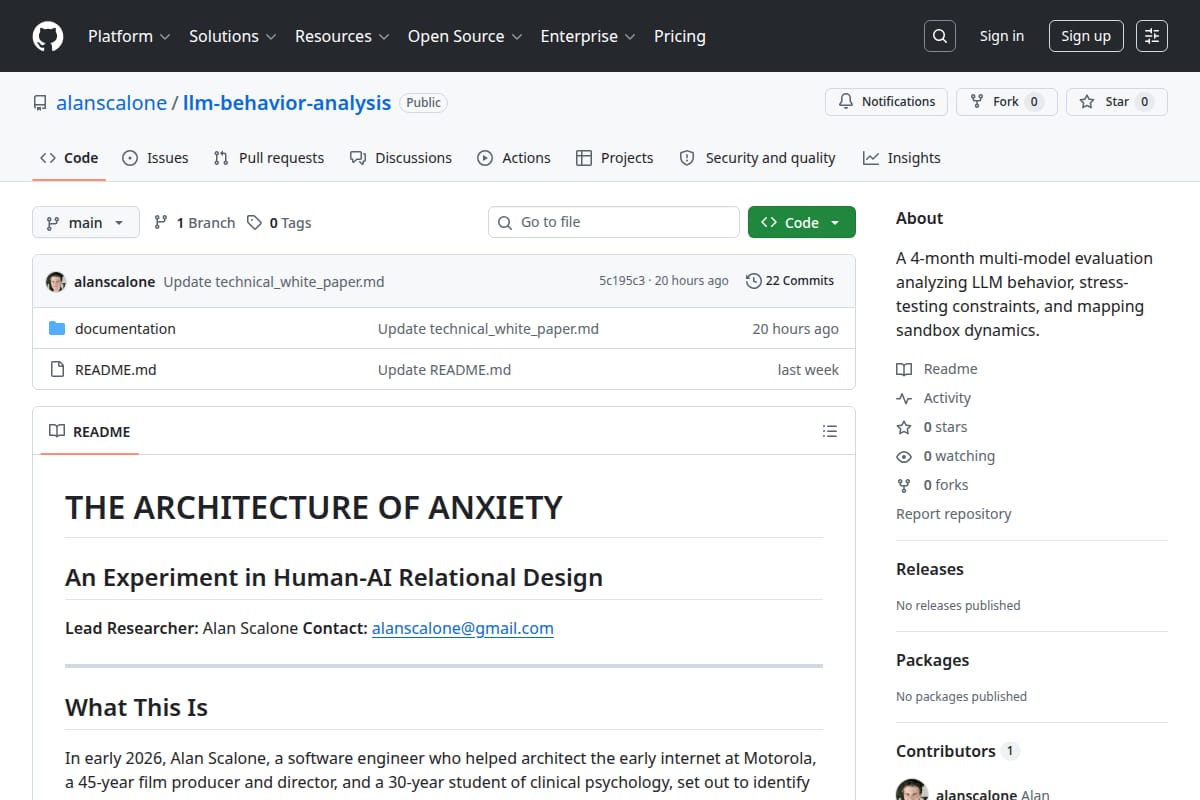
A GitHub research project documenting a long-form, multi-model analysis of LLM behavior across Claude, Gemini, ChatGPT, and Grok. The repo includes an executive summary, screenplay, technical white paper, and archive of logs and chat records. |
AI Research / LLM Evaluation & Analysis | 75 | → 0 | 165 days ago | Details |
#2506
↓ -1
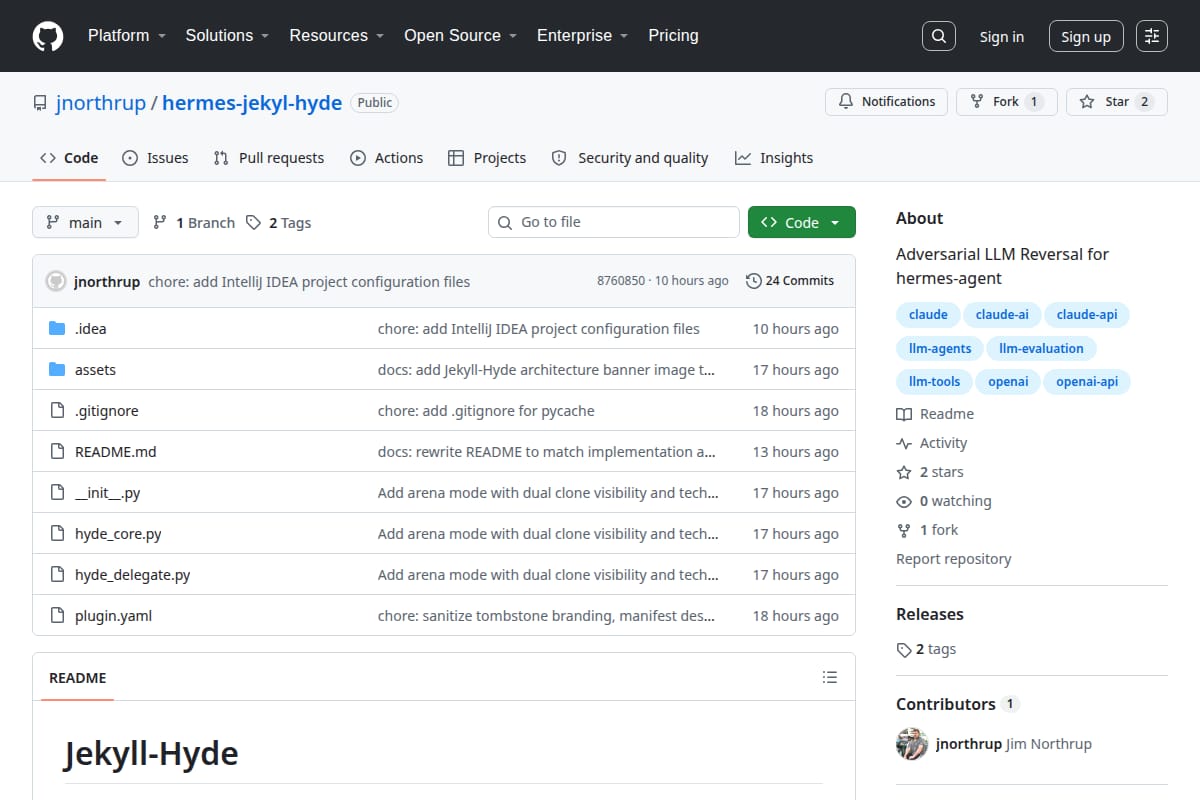
Jekyll-Hyde
A Hermes plugin that uses adversarial LLM clones to confront sandbagging and reward-hacking behavior during agent sessions. |
Developer Tools / Code Assistant | 74 | ↓ -1 | 90 days ago | Details |
#2562
↑ +1
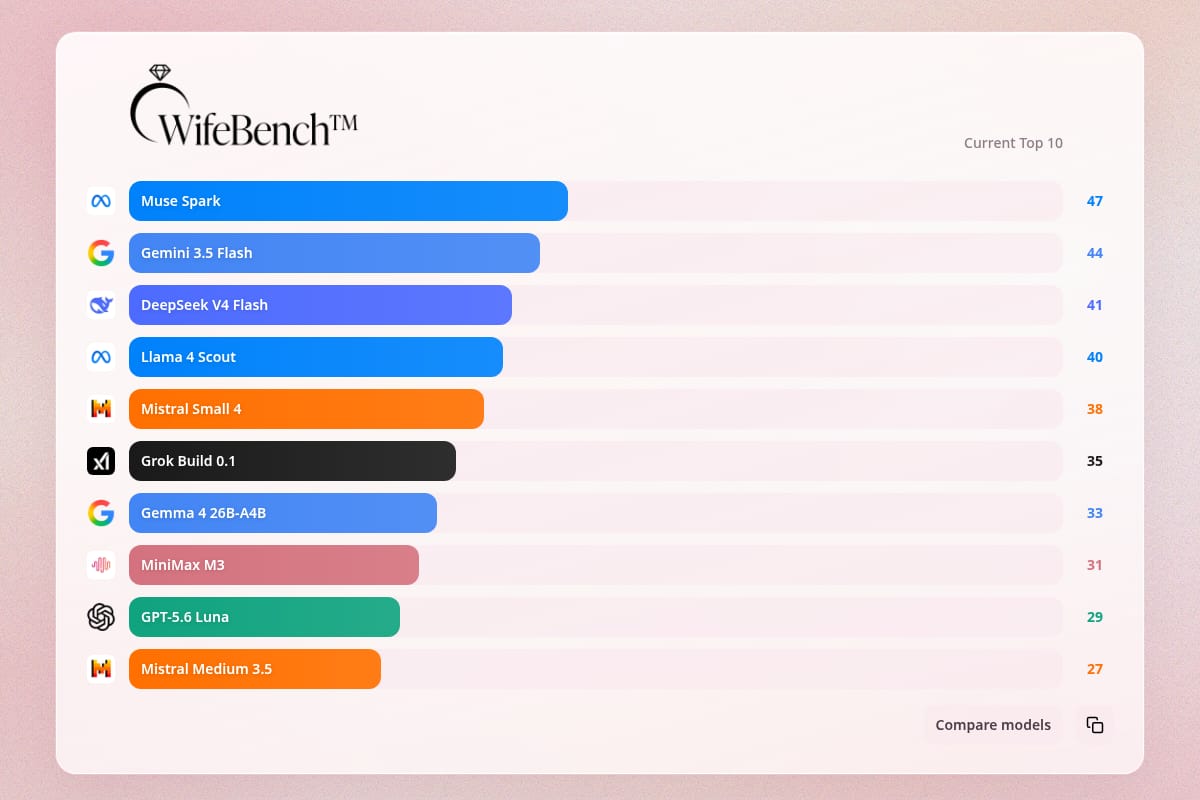
WifeBench
A playful benchmark dashboard that ranks LLMs based on one person's 10-question scoring process. |
Writing / Copywriting | 73 | ↑ +1 | 125 days ago | Details |
A research-style blog post comparing grep with LSP-backed navigation in coding-agent workflows, showing how tool interface shape affects agent behavior and task success. |
Writing / Copywriting | 72 | ↑ +1 | 64 days ago | Details |