
AgentDish directory
Research
Accepted listings with this tag.
| Listing | Category | Score | Trend | Checked | |
|---|---|---|---|---|---|
#1984
↑ +2
Foyer
Foyer is a local dashboard for watching AI coding agents work, with a narrated current-focus view and a research panel for reading sourced briefings while you wait. |
Developer Tools / AI Developer Tools | 81 | ↑ +2 | 149 days ago | Details |
A research article from Plicara Labs analyzing 1.9 million GitHub agent skills and how often they include code, with breakdowns by language, mention-to-code gaps, and writing language. |
Research / Data Analysis | 80 | ↓ -1 | 69 days ago | Details |
#2029
↓ -1
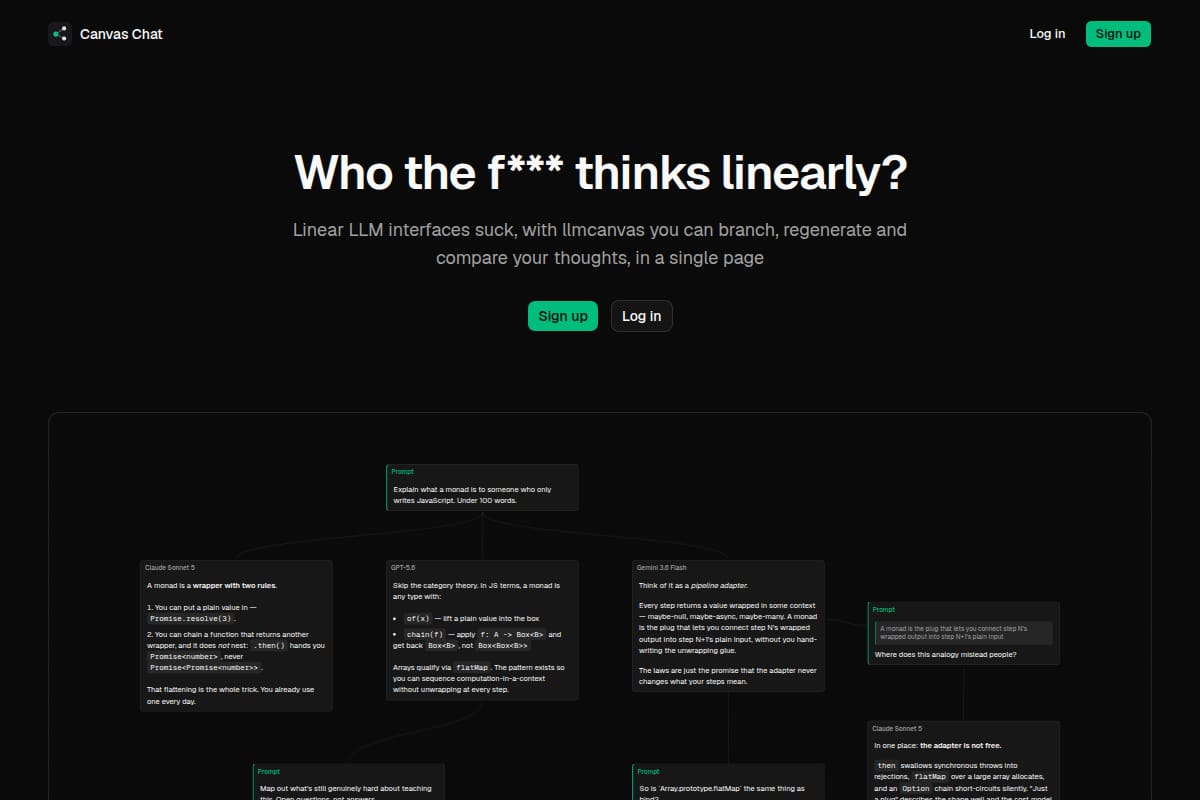
Canvas Chat
Canvas Chat is a tree-based LLM chat interface for branching, comparing, and organizing conversations on an infinite canvas using your own API keys. |
Research / Knowledge Work | 80 | ↓ -1 | 72 days ago | Details |
#2050
↓ -1
Sharper AI
Sharper AI is an AI office assistant that works from your documents and connected apps to research, draft, summarize, schedule, and produce cited deliverables. |
AI Productivity / Office Assistant | 80 | ↓ -1 | 109 days ago | Details |
#2057
↓ -1
Lucid
Lucid is a browser-based tool for inspecting what a language model is representing before it answers, using Anthropic’s Jacobian lens. It supports small open models, lets users type prompts, view concepts across layers, and export shareable session slices. |
AI Tool / Model interpretability | 80 | ↓ -1 | 120 days ago | Details |
#2063
↓ -1
HEADING OS
A Claude Code-based operating system for running executive workflows across research, communications, CRM, content, and operations, with a split between a public engine repo and a private data repo. |
AI Developer Tool / Agent workflow / private data orchestration | 80 | ↓ -1 | 129 days ago | Details |
A data-driven Equibles research piece analyzing 5,305 S&P 500 earnings calls to track how often companies say “agentic,” “generative AI,” and AI developer names like OpenAI and Anthropic. The page includes a summary, methods, and supporting tables/citation info. |
Research / Market Research | 79 | ↑ +2 | 12 days ago | Details |
A GitHub repo for a geospatial benchmark that tests how well six LLMs can classify points in San Francisco from memory and compares results against OpenStreetMap. It includes code, answers, answer keys, costs, and figures for reproducing the analysis. |
Developer Tools / Code Assistant | 79 | ↑ +2 | 19 days ago | Details |
#2105
↑ +2
Site MCP
A web tool that turns a public website into an MCP server so AI agents can search and read its content via a generated link. |
Research / Knowledge Work | 79 | ↑ +2 | 44 days ago | Details |
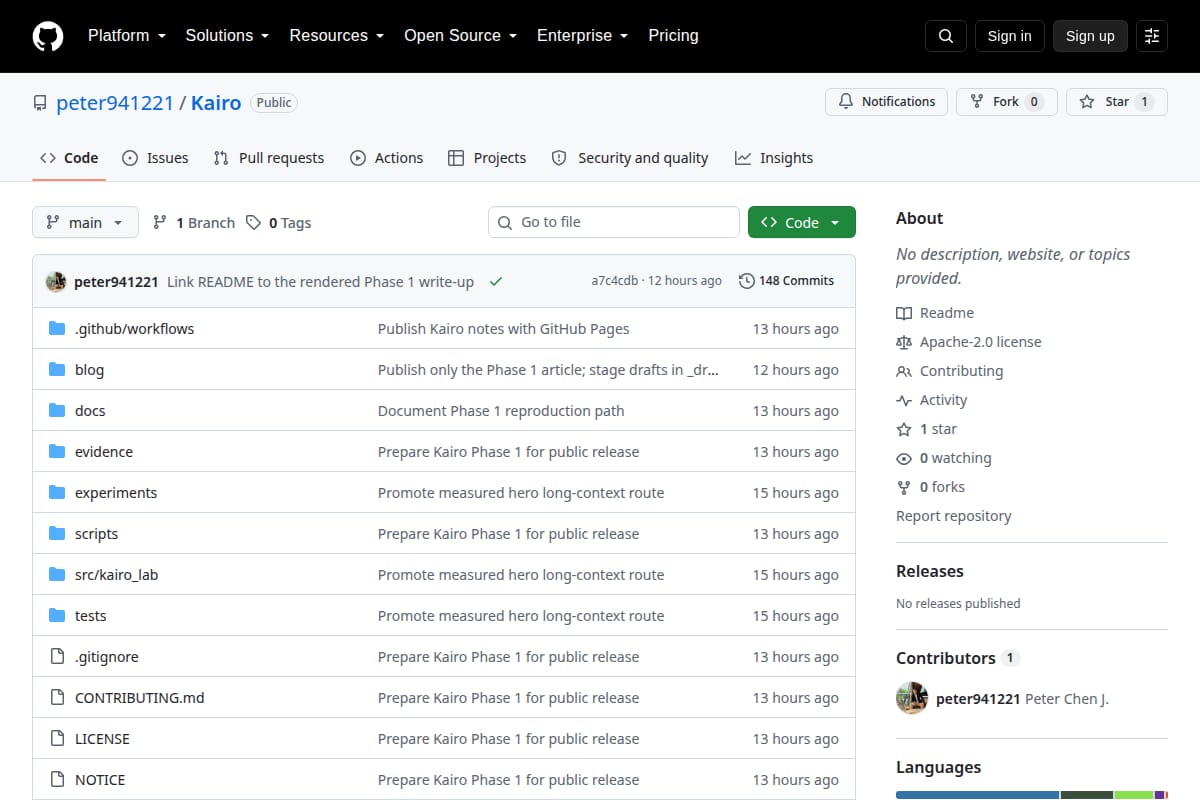
#2110
↑ +2
Kairo
Open-source research workbench for fail-closed LLM inference routing based on measured GPU workloads. The repo documents Phase 1 results, reproducible experiments, quick-start commands, and a policy that only promotes exact measured workload buckets. |
Developer Tools / AI / ML Infrastructure | 79 | ↑ +2 | 54 days ago | Details |
A position paper arguing that AI alignment methods can be repurposed for censorship and manipulation, with examples across pre-training, post-training, and inference-time controls. |
Research / Knowledge Work | 79 | ↑ +2 | 122 days ago | Details |
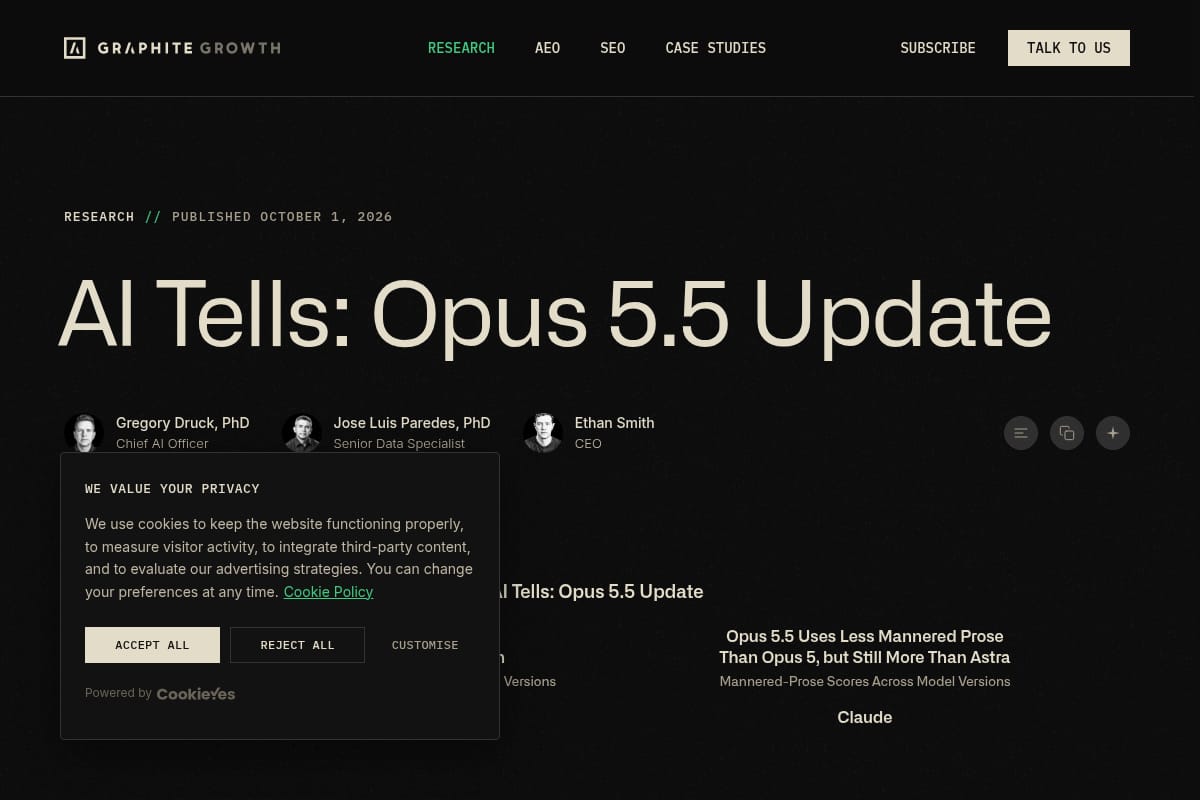
#2200
↑ +6
AI Tells: Opus 5.5 Update
Graphite’s Five Percent research article analyzes writing-style differences in Claude Opus 5.5, compares it with prior Claude versions and GPT-6 Astra, and includes charts, tell counts, and downloadable data. |
Research / AI Model Analysis | 78 | ↑ +6 | 34 days ago | Details |
#2219
↑ +6
Ramanujan
Ramanujan is a terminal-based multi-model agentic workbench for research in computational mathematics. It lets users chat normally, break down problems, survey literature, run parallel subagents, and produce a consolidated report with deterministic checking via SymPy and Z3. |
Developer Tools / AI Agents | 78 | ↑ +6 | 62 days ago | Details |
A DeepMind technical report PDF about double-blind AI evaluations and confidentiality issues in AI safety research. |
Research / AI Safety | 78 | ↑ +6 | 66 days ago | Details |
#2225
↑ +6
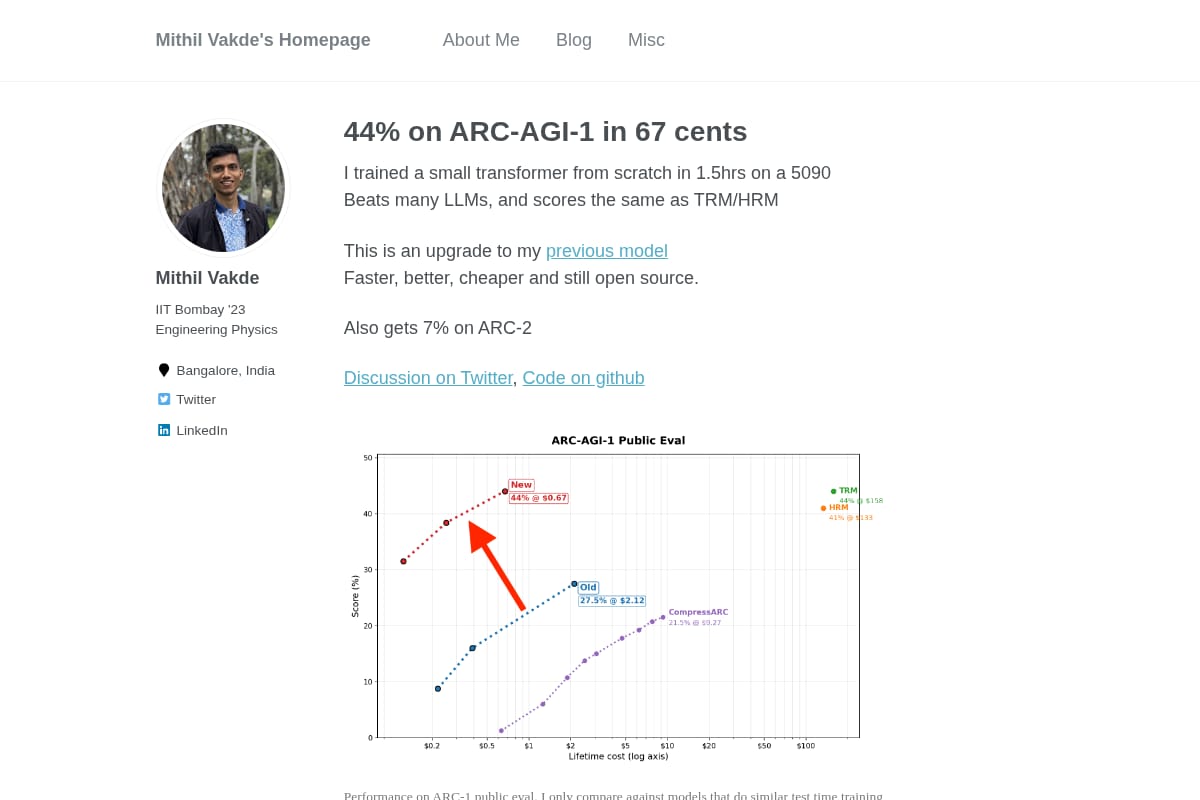
44% on ARC-AGI-1 in 67 cents
A research blog post describing an open-source small transformer trained from scratch to reach 44% on ARC-AGI-1 at very low cost, with architecture notes, ablations, and pointers to code. |
Research / ML Experiment / Benchmark Result | 78 | ↑ +6 | 66 days ago | Details |
#2238
↑ +6
HyperSAE
HyperSAE is a Python package for mechanistic interpretability that trains hyperbolic sparse autoencoders on LLM activations. The page includes installation steps, a quickstart example, benchmark tables, and a short software architecture overview. |
Developer Tools / AI/ML Frameworks | 78 | ↑ +6 | 87 days ago | Details |
A research page on how censorship and behavior transfer during model distillation, with published models, data, evaluation code, and a benchmark called LineageEval. |
Research / AI Safety / Model Behavior | 78 | ↑ +6 | 99 days ago | Details |
#2251
↑ +6
BixRouter
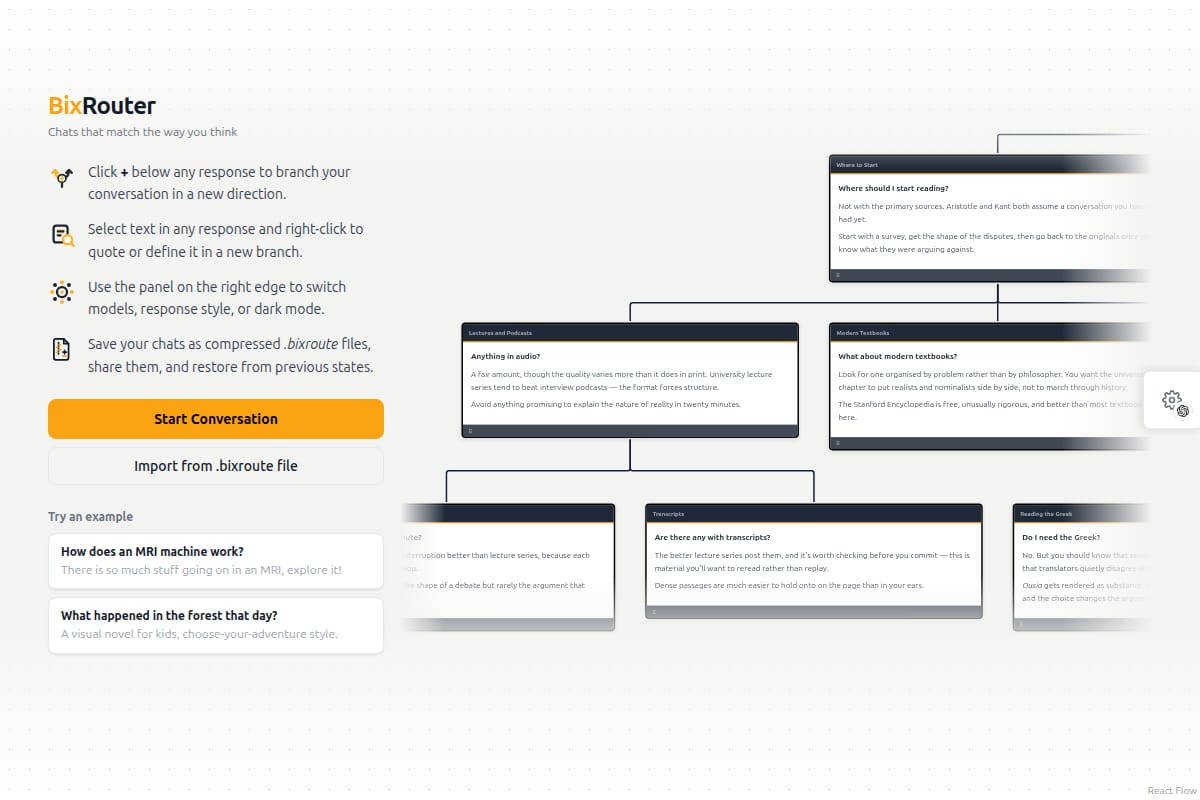
A web app for branching AI conversations into a DAG-style chat tree, with model switching, response style controls, chat import/export, and example conversations. |
Research / Knowledge Work | 78 | ↑ +6 | 102 days ago | Details |
#2306
↑ +6
Agora-1: The Multi-Agent World Model
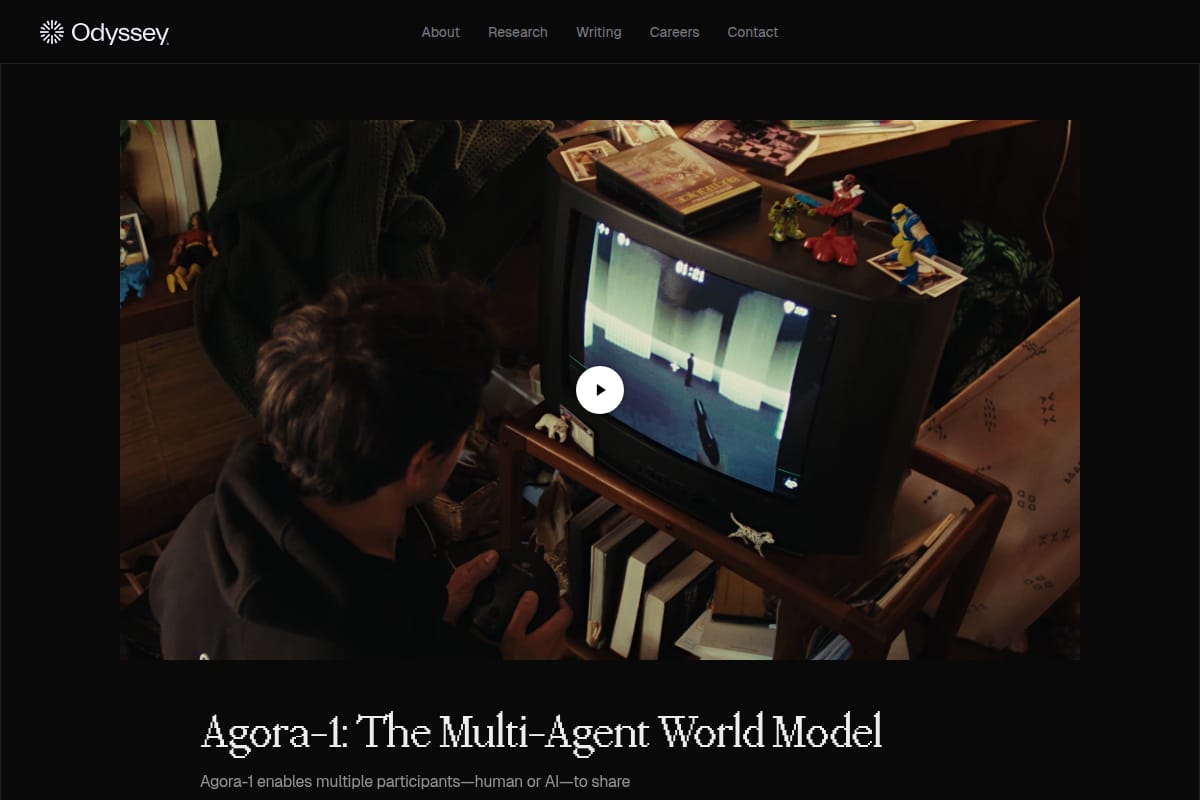
Agora-1 is a multi-agent world model from Odyssey that simulates shared real-time environments for up to four participants, human or AI, with a focus on gaming, robotics, reinforcement learning, and foundation model research. |
AI Research / World Models | 78 | ↑ +6 | 172 days ago | Details |
#2359
→ 0
Prompt Injection as Role Confusion
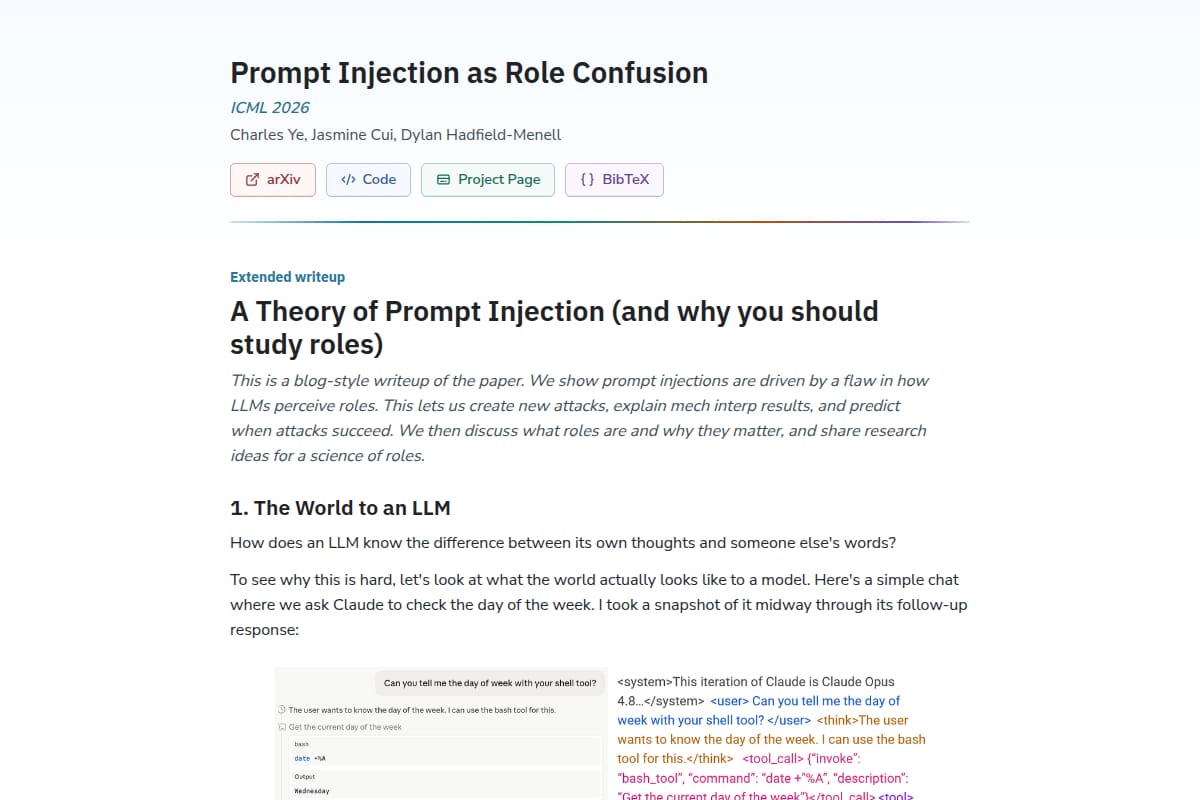
An ICML 2026 research project page arguing that prompt injection comes from how LLMs misread roles, with an extended writeup, examples, and links to the paper, code, arXiv, and BibTeX. |
Research / AI Safety | 77 | → 0 | 137 days ago | Details |
PaperProfit explains an AI-assisted stock evaluation approach that combines fundamentals, technical signals, and qualitative analysis from transcripts and SEC filings into a weighted score. |
Research / Knowledge Work | 77 | → 0 | 158 days ago | Details |
#2368
→ 0
CAPTCHAs can still detect AI agents
A research write-up on detecting AI agents through process differences in CAPTCHA and related cognitive tasks. It outlines the CogCAPTCHA30 approach, reports human-vs-model differences, and connects the findings to Roundtable’s Proof of Human product. |
Research / Knowledge Work | 77 | → 0 | 161 days ago | Details |
arXiv paper on a self-speculative decoding framework for speeding up reasoning LLM inference on edge hardware, with hardware co-design and reported speedups. |
Research / AI/ML Paper | 77 | → 0 | 162 days ago | Details |
Anthropic’s research update on using Claude in drug discovery and life sciences workflows, with case studies from six partner organizations and early results across molecule design, lead optimization, manufacturing, and regulatory work. |
Research / Life Sciences AI | 76 | ↓ -1 | 10 days ago | Details |